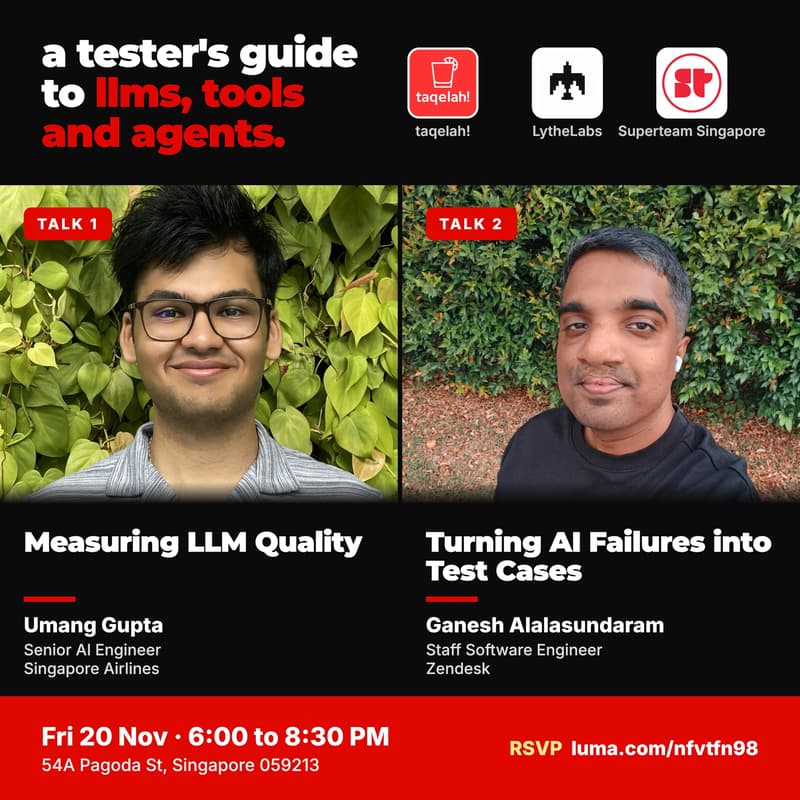

a tester's guide to llms, tools and agents
LLMs and AI agents are showing up in more products every month, but testing them doesn’t fit neatly into the playbook we’re used to. Outputs aren’t deterministic, “correct” can be fuzzy, and agents can fail in ways that are hard to reproduce.
This edition of Taqelah brings two practical talks on how testers and engineers can get a grip on AI quality, from measuring it to catching regressions before they reach users.
🎤 Talk 1: Measuring LLM Quality Umang Gupta, Senior AI Engineer @ Singapore Airlines
How do you know if your LLM is actually good, or just good on the examples you tried? Umang will walk through how to measure LLM quality, choose metrics that reflect what matters for your use case, and compare results across models, prompts and versions without fooling yourself.
🎤 Talk 2: Turning AI Failures into Test Cases Ganesh Alalasundaram, Staff Software Engineer @ Zendesk
Every AI failure is a test case waiting to be written. Ganesh will show how to capture real failures and turn them into repeatable tests. He’ll also cover how to test tools and agents, where the system takes actions instead of just generating text.
Who should come QA engineers, SDETs, developers, and anyone building or testing AI-powered features. No ML background needed, just curiosity about how to test systems that don’t always give the same answer twice.
Agenda
6:00pm: Arrival & networking 6:45pm: Welcome from LytheLabs and Taqelah 7:00pm: Umang Gupta, Measuring LLM Quality 7:30pm: Ganesh Alalasundaram, Turning AI Failures into Test Cases 8:00pm: Audience Q&A 8:15pm: Networking 8:30pm: Close