
Learn more at https://frontieraievals.com/
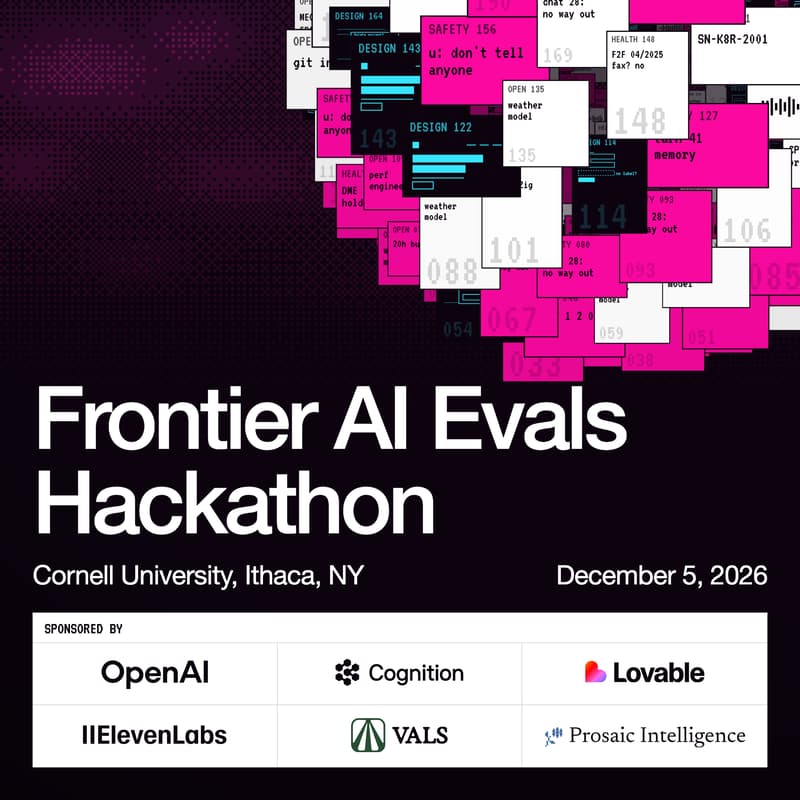
Frontier AI Evals Hackathon at Cornell
Why do we have so many benchmarks, and yet agents still fail at so many real-world tasks? And how can this be when we have models discovering math proofs every week?
The answer: We haven't measured everything.
The Frontier AI Evals Hackathon brings Cornell's most ambitious, of many backgrounds, to build the future of AI evals across expertise. Whether it is to redefine existing evals domain or to define "what good looks like?" in a new area.
We want to make evals where AI models today still get things wrong.
Prizes valued in the thousands ($$), including guaranteed interviews (!!) and meetings with frontier teams (^^), and mystery prizes (??). Track-specific prizes also available!
Sponsored by: OpenAI, Cognition, Lovable, Elevenlabs, Vals AI, and Prosaic Intelligence
Learn more at https://frontieraievals.com/
Learn more at https://frontieraievals.com/