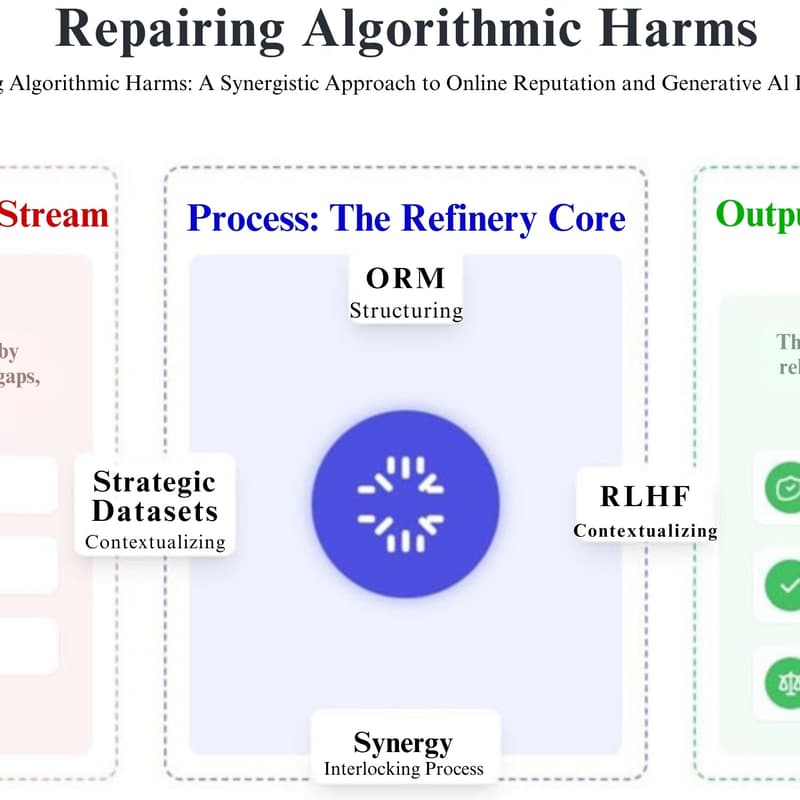
Executive Briefing: The AI Evolution of Online Reputation Management (ORM)
About This Live 30-Minute Briefing & Q&A
When a board member, investor, journalist, or curator vets an individual or organization today, they rarely stop at Page 1 of Google. They ask ChatGPT, Google Gemini, Claude, or Perplexity.
Traditional SEO and online reputation management (ORM) are inherently reactive and fail in generative search because they only operate on the internet's surface-level presentation layer of search results. While pushing down links on Google may hide a link on Page 1, it cannot fix an AI's underlying knowledge layer or core data training sets.
What We Will Cover: The Peer-Reviewed 3-Step GRM Framework
Drawing on his patent-pending methodology and peer-reviewed article published in the Journal of Organizations, Technology and Entrepreneurship (JOTE), Steven W. Giovinco will walk through the divide between core model data vs. surface-level search links and explain how to solve algorithmic injustice and erase AI misinformation using an ethical, evidence-based "wall of truth" (without reputation laundering, fake reviews, astroturfing, or data poisoning) to achieve digital equity and factual accountability[cite: 13, 14]:
Step 1: Digital Ecosystem Curation (Establishing "Ground Truth"): AI models generate an AI hallucination and invent facts when they encounter an information vacuum. Learn how to build a verifiable, machine-readable digital moat wrapped in schema markup across the websites AI trusts most: a centralized web hub, blog articles, verified wikis, Reddit and Quora posts, Wikipedia, industry-aligned forums, and real photos and videos with metadata.
Step 2: Direct LLM Correction via Verifiable Human Feedback: How Generative Reputation Management (GRM) utilizes direct Reinforcement Learning from Human Feedback (RLHF) to systematically execute LLM correction, focusing on correcting LLM outputs inside ChatGPT and Gemini by citing the ground truth architecture built in Step 1.
Step 3: Strategic Dataset Curation (Long-Term AI Inoculation): How transforming verified records into structured datasets published on sites like ResearchGate fortifies a digital identity so future AI models are hardwired with factual accuracy from day one.
Documented Before-and-After Case Studies
We will review real-world before-and-after screenshots demonstrating how this process fixes LLM hallucinations, mitigates information vacuums, and uses entity disambiguation to solve exact-match naming collisions, including how Recover Reputation transformed a Hedge Fund CEO's digital footprint from a Gemini information vacuum to a positive summary, and countered a malicious disinformation campaign against a Global Sustainable Energy Group by directly repairing ChatGPT's underlying training data.
Preview the JOTE Study & Case Studies: https://www.recoverreputation.com/blog/generative-reputation-management-grm-the-peer-reviewed-framework-for-erasing-ai-misinformation/
Run a Free Live AI Diagnostic on Any Name or Brand: https://www.recoverreputation.com/#grm-widget-root