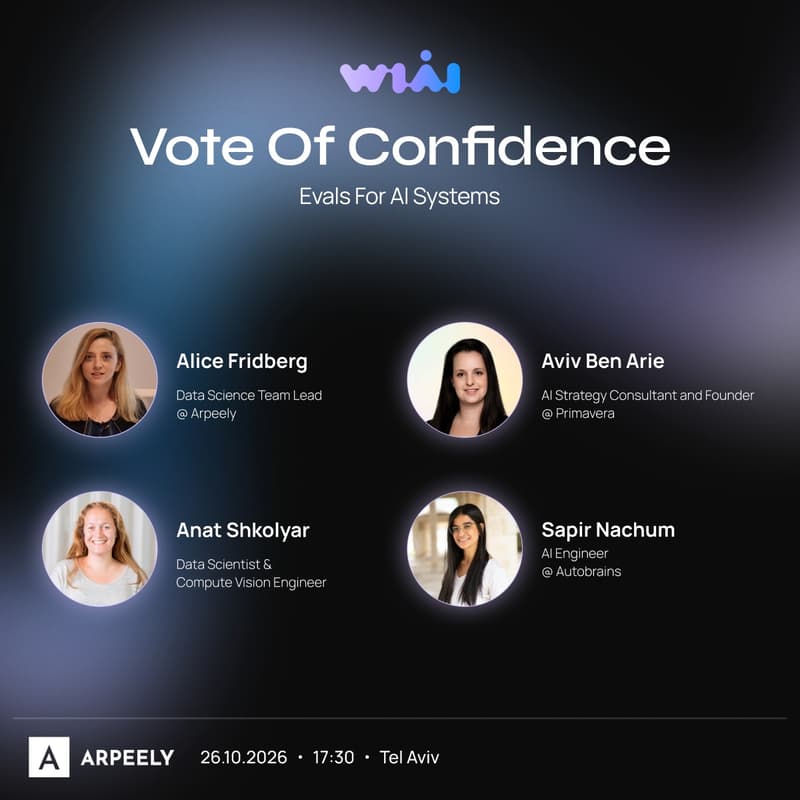
Vote of Confidence: Evals for AI Systems
Meetup Itinerary
17:30 - 18:00 Gathering end registration
18:00 - 18:15 Opening Remarks / Alice Fridberg, Data Science Team Lead, Arpeely
18:15 - 18:45 How Do You Know What Your Model Doesn’t Know / Sapir Nachum Magnezi
18:45 - 18:55 Break
18:55 - 19:25 Beyond the Vibe Check: Building Lean, Modern Eval Benchmarks for Your AI Agents / Aviv Ben Arie
19:25 - 19:55 Monitoring in production systems / Anat Shkolyar
Talks Abstract:
How Do You Know What Your Model Doesn’t Know?
Sapir Nachum Magnezi| AI Engneer at Autobrains
A better KPI score doesn’t always mean a better system in production. How do we uncover weaknesses hidden behind aggregate metrics, decide which failures actually matter, and know when our evaluation is no longer trustworthy?
In this talk, we’ll explore the eval process-from identifying and prioritizing model weaknesses to using explainability and error analysis to make better development decisions, ensuring we focus our efforts on the problems that actually matter
Beyond the Vibe Check: Building Lean, Modern Eval Benchmarks for Your AI Agents
Aviv Ben Arie | AI Strategy Consultant and Founder at Primavera
Building an AI agent in 2026 is easy; proving it is production-ready is still incredibly hard. When dealing with non-deterministic agentic workflows, traditional unit tests fail and generic metrics are too shallow. To deploy with confidence, you need a custom evaluation benchmark. But how do you build one without drowning in months of manual work? In this fast-paced, 15-minute session, we’ll skip the theory and look at a lean, generalized framework for spinning up agentic eval benchmarks quickly.
The World Changes, Your Model Does Not - Monitoring Models in Production
Anat Shkolyar | Data Scientist and Computer Vision Engineer
The world keeps changing after your model ships. Through two examples drawn from real-life systems, this talk shows what to monitor in production, how metrics can lie, and how to catch problems before your customers do.