
Building the future of Physical AI in Berlin
BRISA Reading Group 08 - VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model
This Monday we are looking at VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model (Guo, Lee, Shi, Chen, Liang & Finn, 2026) from Stanford and Tsinghua, presented at ICML 2026.
Two weeks ago, Long-WAM built prediction into the policy itself. VLAW keeps policy and world model separate and asks whether each can make the other better.
Improving a robot policy through practice means running it again and again on real hardware, which is slow and expensive. A learned world model could stand in as the simulator. However, today’s world models are trained mostly on successful demonstrations: they are too optimistic and they miss the small physical details that decide whether a contact-rich task works.
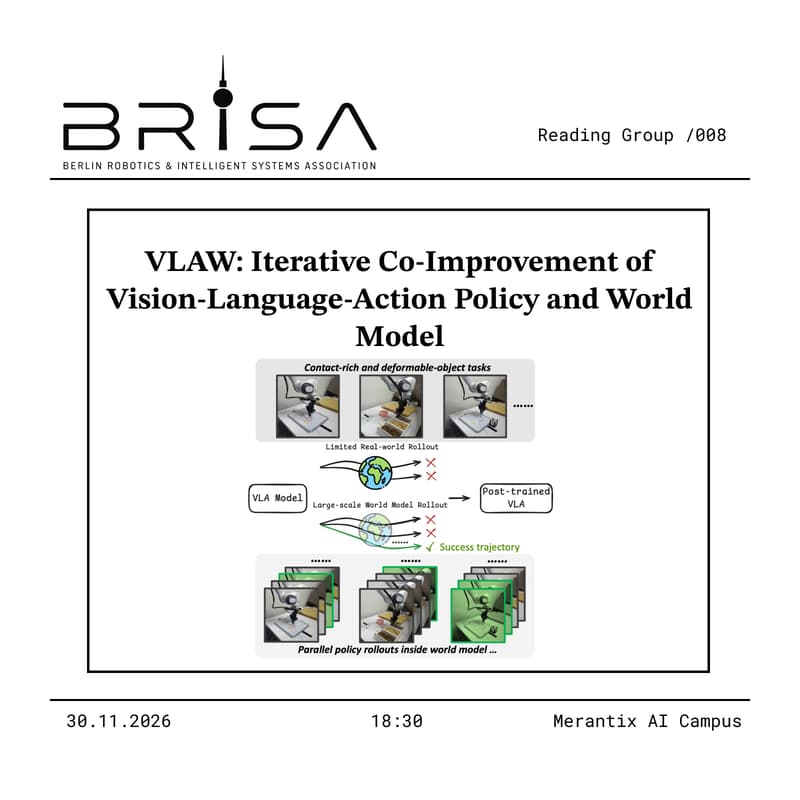
VLAW closes the loop, by rolling out the policy (π0.5) on a real Franka arm (failures included). Those rollouts finetune the world model. The policy then practises inside the improved world model at scale, a vision-language model judges which imagined attempts succeeded and the policy is finetuned on the successful real and synthetic ones.
Across contact-rich tasks like scooping, erasing marks and stacking, this improves success by 39.2 percentage points over the base policy, with 11.6 of those coming from the synthetic rollouts.
As always: No preparation needed.
Come with questions, disagreements, or your own take on how much a robot can learn from its own imagination.
🎟️ There are only a limited number of spots, so we can keep the session personal and interactive. Please register early and only attend if you’ve received a ticket.
📍 Hosted at the Merantix AI Campus on November 30th. Doors open 18:30, we start at 18:45.
👋 New here? Join the community group - everything else gets announced there first.
Building the future of Physical AI in Berlin