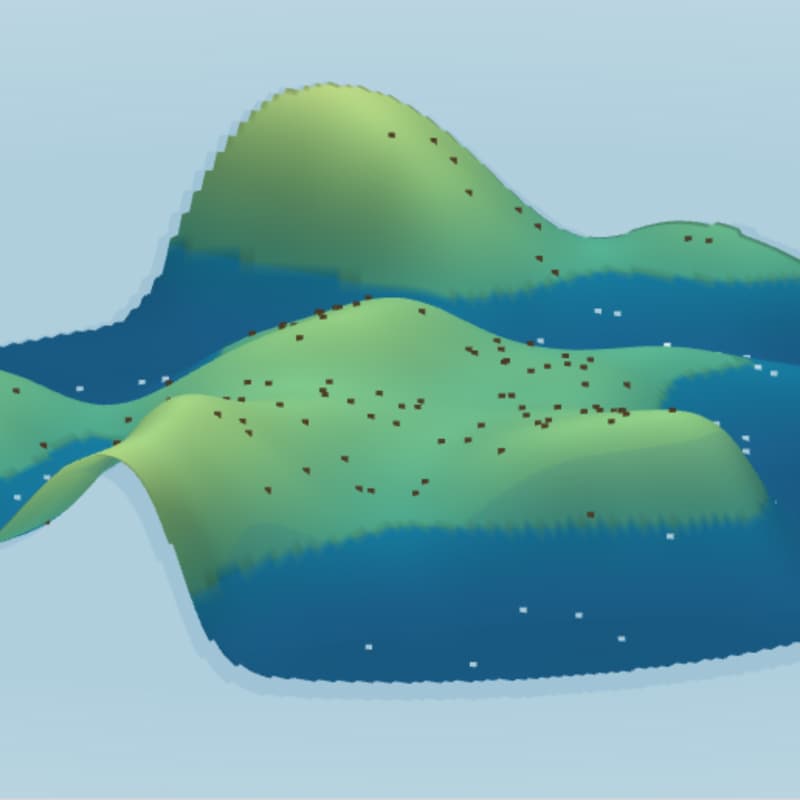

How Good are Frontier Models, really? Surveying Performance across SoTA Agentic Tasks from Web Browsing to Robotics
Manifold is thrilled to welcome Yangyue Wang from the Fig.inc Research team for a live research talk on mapping the jagged performance of frontier models across agentic tasks.
In this work, we ran Astra, Opus 5.5 and other frontier models on digital and physical tasks, including domains like: web search, driving, industrial procedures, assembly, and self driving tasks. We found surprising jagged shapes everywhere.
Across the six browser models, every lower-scoring model solves tasks a higher-scoring one fails. One model update moved the average by 1.1 points while flipping 36 of 177 task outcomes.
We will cover:
why a benchmark average cannot tell you where an agent fails
how we measured on two axes: six models on one browser domain, one model pair across four physical domains
what task-level results show that an average score hides, across models, model updates and domains
open problems in continual learning and in evaluation for agent reliability.
what Fig is building next, and how to get involved
The talk will be followed by an open Q&A and discussion.
Sign up to stay in the loop on Fig.inc's Research
Check out the Fig Team's recent technical report
Explore opportunities at Manifold: https://www.manifoldrg.com/opportunities/
Join the Advancement Network: https://www.manifoldrg.com/advancement-network/
Subscribe to our Luma calendar for future talks: https://luma.com/manifold