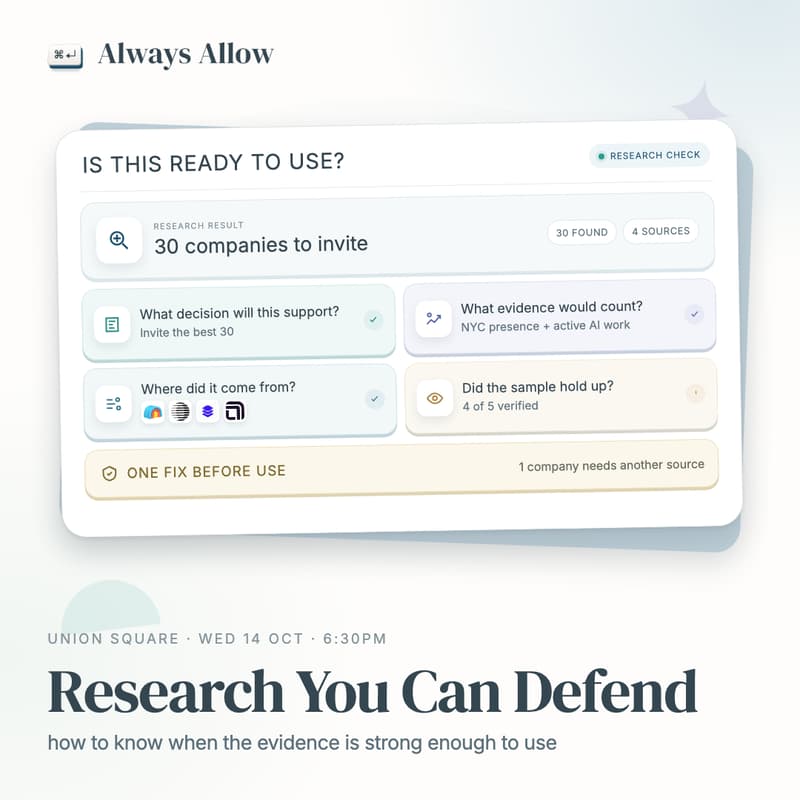

Research You Can Defend
Someone asks you to use AI to research a market, build a prospect list, or recommend who to contact, and the answer arrives looking finished. The problem is that “looks right” isn’t an evaluation standard. Before anyone uses the work, you need to know what decision it supports, what evidence would make it credible, and what still depends on human judgment.
In this workshop, we’ll build an evaluation framework for one research workflow. We’ll use historical examples and outcomes to identify what evidence matters, decide where it should come from, and test a small sample before calling the result ready. Along the way, we’ll compare what Claude or ChatGPT can do on their own with live web research, data providers, scraping, and human expertise.
Walk away with a research workflow you can explain and defend, plus a clear standard for deciding when its evidence is strong enough to use.
Always Allow is hands-on AI strategy and training for people who learn by building. If you’ve ever used AI and thought, “I know I can get more from this,” you should join us.