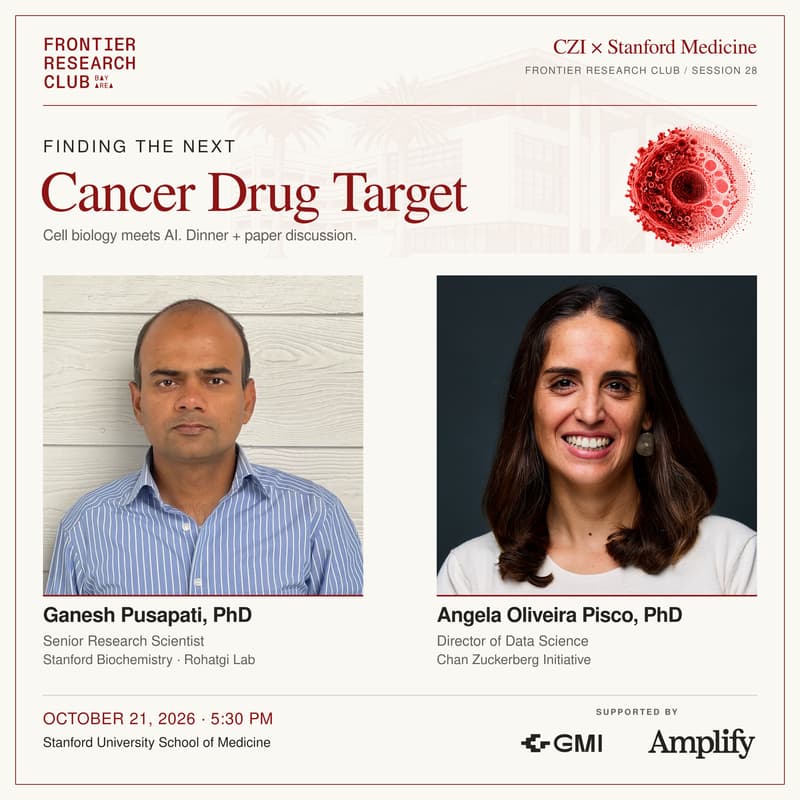


Bay Area Frontier Research Club #28 | CZI × Stanford Medicine: Finding the Next Cancer Drug Target (dinner + paper discussion @ Stanford)
How do we go from understanding what goes wrong inside a cell to finding where a drug could intervene—and can AI help us get there faster?
This evening at Stanford brings together a new discovery in colorectal cancer and the effort to build virtual cells that could help researchers decide which interventions to test next.
Ganesh Pusapati, PhD, a Senior Research Scientist in Stanford Biochemistry’s Rohatgi Lab, co-led a study published in Nature Genetics this July that uncovered a new therapeutic vulnerability in colorectal cancer. His team identified roughly 150 previously unreported mutations affecting the destruction complex, the machinery that keeps WNT/β-catenin signaling in check. They then showed that restoring its function reduced cancer-cell growth in the lab. He’ll take us through the experiments that revealed this vulnerability and what the findings could mean for future treatments.
Angela Oliveira Pisco, PhD, is Director of Data Science at the Chan Zuckerberg Initiative and previously led computational biology and machine learning for omics at insitro. At CZ Biohub, she helped build major cell atlases, including Tabula Sapiens. She’ll explore what AI can learn from these vast collections of cellular data—and what evidence we need before trusting a virtual cell to help guide drug discovery.
Join us for dinner, two short research talks, and extended Q&A with both speakers. We’ll discuss how an unexpected biological finding becomes a therapeutic hypothesis, where computational predictions can help, and which experiments would convince us to pursue a target. Bring your questions: most of the evening’s research program is reserved for discussion.
The Frontier Research Club is a curated forum for rigorous, technical discussion at the frontier of AI. We convene researchers from the frontier labs, Stanford, Berkeley, and the teams building in production to examine concrete work — papers, methods, and results — with a bias toward assumptions, evaluation methodology, failure modes, and what would count as convincing evidence.
Each session features 2 talks selected for rigor and discussion value. Presentations are intentionally brief so the majority of time is reserved for questions and critique. Papers and supporting materials are shared in advance to ensure a high-baseline conversation.
Agenda
5:30 PM — Doors open
5:30–6:30 PM — Networking + light dinner
6:30–6:40 PM — Group photo and intro remarks
6:40–7:10 PM — Talk 1 + Q&A
7:10–7:40 PM — Talk 2 + Q&A
7:45–8:00 PM — Guided discussion with both speakers
8:00–8:45 PM — Networking
Presenters and topics
Talk 1 — Repairing a Broken Molecular Machine in Colorectal Cancer
More than 80% of colorectal cancers are driven by mutations in APC, a key component of the destruction complex—the machinery that normally keeps WNT/β-catenin signaling in check. Ganesh’s recent work reveals a surprising feature of this damaged machine: the protein it is supposed to destroy also helps hold it together.
Ganesh will trace that discovery from genome-editing screens to biochemical experiments, showing how changes at individual DNA bases revealed an unexpected opportunity to intervene. By strengthening the interaction between two components, his team restored the complex’s function and slowed cancer-cell growth in the lab. The findings offer a proof of concept for a therapeutic approach: repairing the machinery that cancer has disrupted.
Pre-read: Mutational scanning reveals substrate-assisted autoregulation of the WNT destruction complex, Nature Genetics (July 2026) — https://www.nature.com/articles/s41588-026-02662-3
Ganesh Pusapati, PhD, is a Senior Research Scientist in Stanford University’s Department of Biochemistry, in the Rohatgi Lab. He co-led the study published in Nature Genetics in July 2026. He earned his PhD at the University of Ulm and completed postdoctoral training at Stanford with Suzanne Pfeffer and Rajat Rohatgi.
Talk 2 — The Virtual Cell: What Can AI Predict?
Can a model trained on single-cell data predict what happens when you knock out a gene or add a drug—in a cell type it has never seen perturbed? If it can, the virtual cell becomes a way to choose experiments and rank targets before anyone touches a bench. If it can’t, it’s an expensive lookup table.
Angela helped build the atlases these models learn from: Tabula Sapiens, a reference of nearly 500,000 cells across 24 human organs, and the CZ CELLxGENE corpus, now tens of millions of cells. She’ll show what today’s models actually learn from data at that scale, where their predictions hold across tissues, diseases and perturbations and where they fall apart, and what evidence a drug-discovery team should demand before trusting one—including where the experiment still has to be run.
Pre-reads: The Tabula Sapiens: a multiple-organ, single-cell transcriptomic atlas of humans, Science (2022) — https://www.science.org/doi/10.1126/science.abl4896 (free full text: https://pmc.ncbi.nlm.nih.gov/articles/PMC9812260/) · CZ CELLxGENE Discover — https://cellxgene.cziscience.com
Angela Oliveira Pisco, PhD, is Director of Data Science at the Chan Zuckerberg Initiative, where she develops tools and models to better understand disease mechanisms. She previously led computational biology and machine learning for omics at insitro and directed the data science platform at CZ Biohub San Francisco, contributing to major cell atlas projects including Tabula Muris and Tabula Sapiens.
Guided discussion
Both speakers join Aaran Vijayakumaran of Stanford Biochemistry for a discussion about how experimental discoveries and AI predictions can guide one another. Which biological mechanisms must a model capture? What would make a prediction worth testing? And what evidence would justify pursuing a new drug target?
We’ll then open the conversation to the room for questions, challenges, and perspectives from attendees’ own work.
Want to present your work?
Frontier Research Club is built around researchers willing to put concrete work in front of a technically serious room. If you have a research paper you would like to discuss at an upcoming session, submit it for consideration.
Submit your paper here
Who should attend
Experimental biologists working across cancer biology, functional genomics, perturbation screens and wet-lab systems
Computational biologists and bioinformaticians working with single-cell and atlas-scale data
ML researchers building foundation models, generative models and benchmarks for biological data
Drug-discovery and translational teams from biotechnology and pharmaceutical companies
Research engineers and laboratory-automation teams building the layer between the model and the bench
Founders building in AI × bio and the investors backing them
Capacity is limited.
We will take photos and short video clips for event recap and promotion. By attending, you consent to being photographed and recorded, and to the use of those images and clips by the organizers on social media and other event marketing channels.
🌐 Connect with Frontier Research Club
Luma Calendar: luma.com/frontiersyndicate
YouTube: FrontierResearchClub
LinkedIn: frontier-research-club
Instagram: @frontierresearchclub
Email: kristopher@frontiersyndicate.vc
Hosted by
The Frontier Syndicate is a venture community connecting frontier-technology researchers, builders and investors through curated convenings and early-stage capital. Across the Bay Area, we produce a recurring series of research forums, builder nights and intimate investor dinners — and back exceptional companies emerging from the laboratories, communities and technical networks we convene.
Dinner by Amplify Partners
Amplify Partners backs technical founders from the earliest stages, with a dedicated bio platform for companies building at the intersection of AI and life sciences. Founding GP Sunil Dhaliwal and the Amplify bio team will be in the room tonight. If you’re a researcher thinking about starting a company, or a founder already building one, find them at dinner. → amplifypartners.com
Compute by GMI Cloud
GMI Cloud is an AI-native GPU cloud built for training and inference at scale, running its own NVIDIA infrastructure across data centers in the US and Asia. For teams turning atlas-scale data into models, the question after tonight’s talks is what you train on — GMI is here to talk about that. → gmicloud.ai