
The Decision on Decision Models: What They Do to Your Agent's Memory
Six weeks ago there was one decision model. Now there are more than fifty: TypeSafe's Jev, Cloudflare's Clef, Perplexity's decider, AWS's Strands Decider, Stanford and NVIDIA's CLM, and OpenAI's Decisions API. Most of the coverage compares them on a leaderboard. I want to answer a narrower question: what happens to an agent's memory system when you put one in?
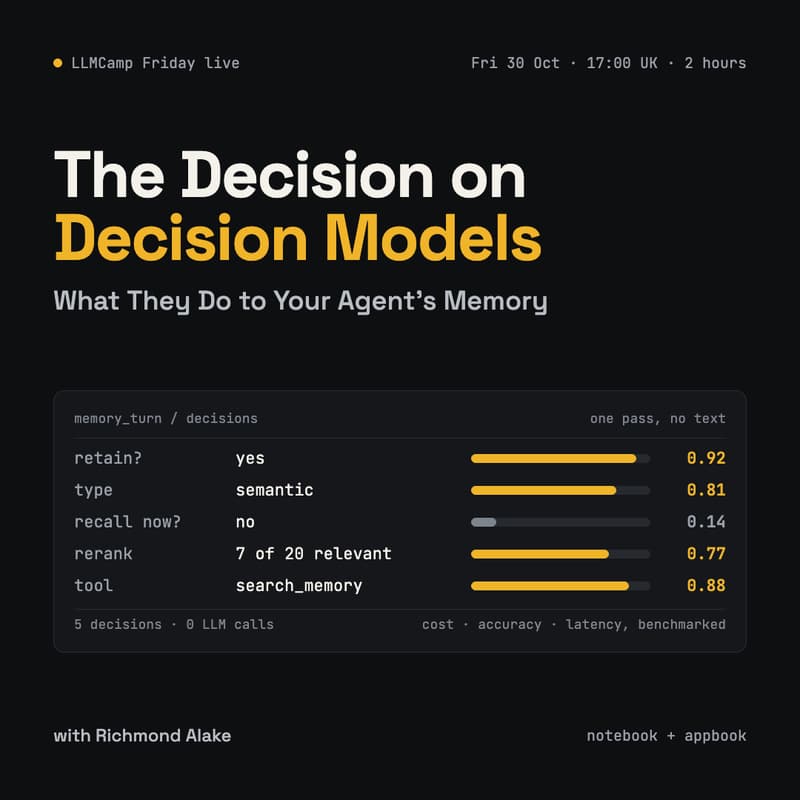
Most memory operations are decisions. Is this worth retaining? Which store does it belong in? Should the agent recall anything on this turn? Which of these twenty candidates matter? Which tool? Today most teams answer each of those with a frontier LLM call, which is why memory is usually the slowest and most expensive part of the harness.
In two hours I'll cover:
What a decision model is, and what it isn't (not structured outputs, not a classifier you trained)
The architecture: frozen backbone, prefill only, a 256 MB head, and why that is the whole latency story
The System 1 ecosystem: who ships what, hosted versus open weights, and where OpenAI's Decisions API sits
The Hugging Face Decision Index and how to read it without being misled
An agent memory reference architecture with an LLM or a heuristic at every decision point, then the same architecture with decision models swapped in
Benchmarks on the parts that changed: semantic chunking, reranking, memory routing and tool search, measured on cost, accuracy and latency
Technical resource: a notebook and an appbook, shared in the LLMCamp GitHub repo after the session.
Who it's for: AI engineers, AI architects, forward deployed engineers and product managers building agents with memory who want to know which decisions to take off the LLM.
Streaming live on YouTube and LinkedIn, and the recording goes up on YouTube afterwards. You'll leave knowing which memory operations to hand to a decision model, which to keep on the LLM, and what it costs either way.