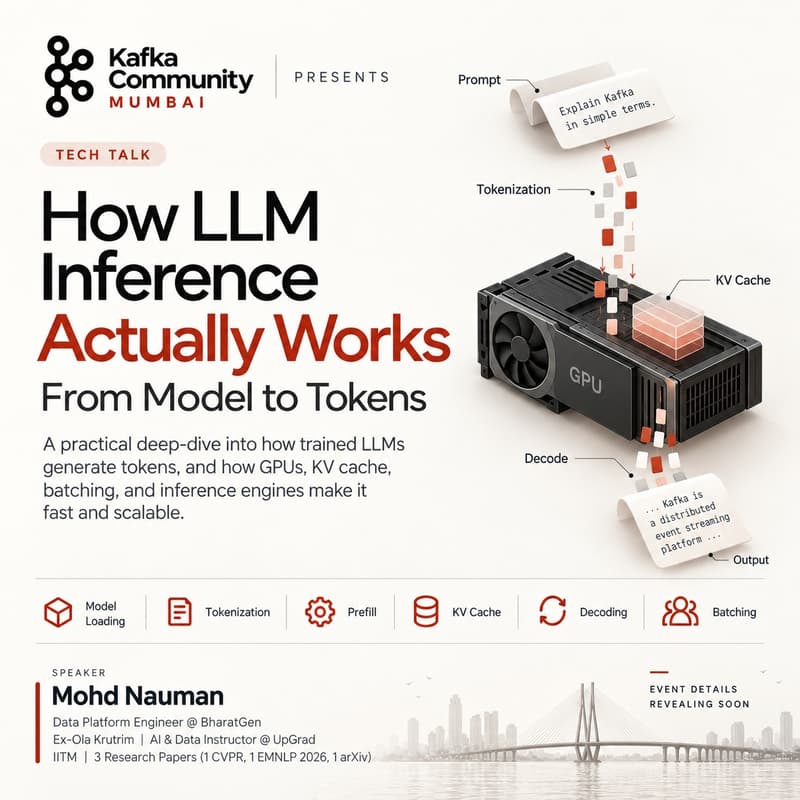
Inside LLM Inference: From Model Weights to Tokens at Scale
Ever wondered what actually happens after you hit Send on ChatGPT?
We talk a lot about training LLMs, building AI agents, and using APIs. But how does a trained model actually generate tokens? What happens inside the GPU? And how do inference engines serve thousands of requests efficiently?
In this session, we'll break down LLM inference from the ground up-starting with model weights and token generation, then exploring the engineering challenges of running LLMs in production.
We'll cover:
From Model to Inference: How a trained model is loaded and generates its first token.
Inside Token Generation: Embeddings, attention, prefill, decoding, and autoregressive generation.
KV Cache: Why it matters and how it affects memory and performance.
GPU Memory & Compute: What limits inference speed and how model size and context length affect resource requirements.
Scaling Inference: Batching, continuous batching, and how engines like vLLM serve concurrent requests.
We'll also explore practical trade-offs between latency, throughput, memory utilization, and cost.
Who should attend?
Developers, AI/ML engineers, students, and anyone curious about what happens beyond an LLM API call.
No deep ML background required. A basic understanding of programming is enough.
Join us to understand not just how to call an LLM, but how to actually run one efficiently.