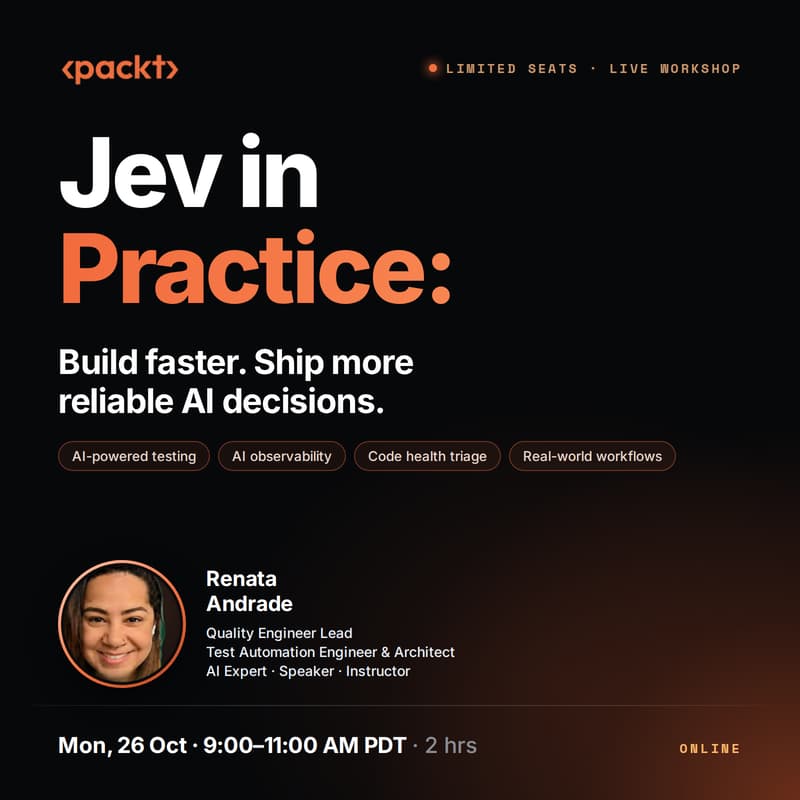

JEV in Practice: Build Faster, More Reliable AI Decisions
About the event
Stop paying an LLM to answer yes/no questions. Build three real decision layers with Jev in two hours.
Your pipeline asks hundreds of small questions every day. Is this test result suspicious? Which code issue matters most? Is this AI feature worth its token bill? Most teams throw a large LLM at every one. There's a faster way.
Not every AI problem needs another LLM call
Generative models are great at writing, but they're slow, costly and unpredictable when all you need is a decision your code can act on.
Jev is built for exactly that. You give it state, ask a typed question, and get back a structured decision with a confidence score. Your application can branch, rank or route on that answer directly. Think of it as a fast "System One" model that works alongside your LLMs rather than replacing them.
This workshop takes Jev beyond the API demo. You'll build three different projects and see how the same decision primitives solve very different engineering problems.
What you'll build
Project 1: Exploratory testing with Jev + Playwright (hands-on)
Point Jev at a live application through Playwright and turn what it observes into confidence-aware verdicts. You'll get a test flow that tells you when something looks off and when to escalate, instead of a wall of brittle assertions.
Project 2: Code health triage with RepoWise / CodeScene
Feed in static-analysis findings and let Jev classify, score and prioritise them. You'll get a decision layer that shows your team what deserves engineering attention first, so nobody has to review every issue by hand.
Project 3: AI observability
Measure token cost, model usage and real impact, then use Jev to judge whether an AI workflow is earning its keep. You'll get a way to back "is this worth it?" conversations with data.
Agenda (2 hours, live)
0:00 – 0:30: What Jev is, its architecture, how it compares with LLMs, and Jev vs Laya
0:30 – 1:00: Project 1, exploratory testing with Jev + Playwright
1:00 – 1:25: Project 2, code health triage
1:25 – 2:00: Project 3, AI observability, plus live Q&A
You'll leave with
Working code for all three projects
A reusable "decision layer" pattern you can drop into your own pipelines
A clear rule of thumb for when to use Jev and when to reach for an LLM
Workshop recording
Certificate of completion
Who should attend
QA engineers, SDETs and test automation engineers
Engineering leads tired of drowning in tech-debt findings
Platform and DevEx engineers building smarter CI pipelines
AI engineers who want to cut LLM cost and latency
Anyone who has asked "do we really need GPT for this?"
Meet your instructor
Renata helps engineering teams build quality into how they work, in the easiest, fastest and most reliable way possible. She brings a tester's instinct to AI: don't just ask whether it works, ask whether you can trust the answer, and what it costs to find out.
Renata Andrade
Quality Engineer Lead · Test Automation Engineer & Architect · AI Expert · Speaker · Instructor