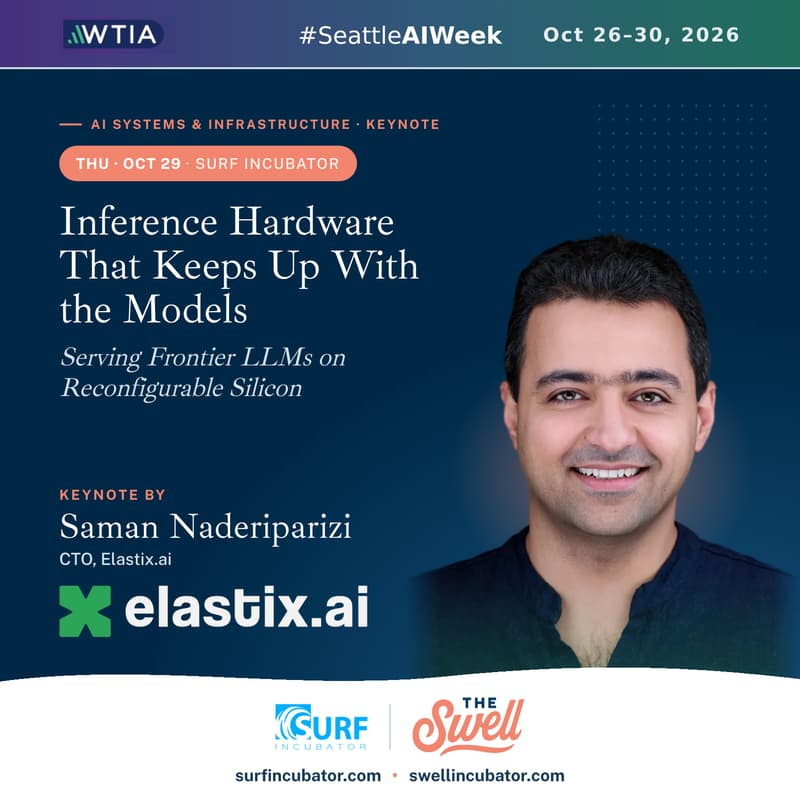

Inference Hardware That Keeps Up With the Models: Serving Frontier LLMs on Reconfigurable Silicon
Frontier LLMs are getting bigger and changing shape faster than the chips built to run them. The result is inference that costs too much, runs too slow, or both.
Saman Naderiparizi CTO of Elastix.ai will walk through why legacy inference accelerators hit a wall with today’s models, and how reconfigurable silicon changes the math. This is a 30-minute technical talk for people who build, deploy or pay for AI infrastructure.
What you’ll take away:
Where the bottlenecks are: why fixed-function accelerators struggle as model architectures evolve
How reconfigurable silicon works: dynamic hardware flexibility that adapts execution to the model at runtime
What this means in production: practical approaches to cutting latency and raising throughput at scale
Who this is for: ML engineers, infrastructure leads, CTOs and technical founders running or evaluating LLM inference.
Speaker: Saman Naderiparizi, Elastix.ai
Format: 30-minute talk with time for questions
Track: AI Systems & Infrastructure
AI Systems & Infrastructure day is made possible with the support of Elastix.ai.
Elastix.ai is a Seattle startup building inference infrastructure for frontier LLMs on reconfigurable silicon. Founded by former Apple and Meta machine learning engineers, Elastix runs large models on off-the-shelf FPGA servers that fit a standard air-cooled rack and plug in through a vLLM back end with an OpenAI-compatible API. The company reports up to 50x lower total cost of ownership and 80% less power than GPU deployments. Learn more at elastix.ai.
Part of SURF x SWELL Seattle AI Week. Full calendar at luma.com/surfaiweek
FAQ:
Q: Is there on-site parking?
Yes, secure garage parking is available $10 parking pass is available from the front desk at SURF Incubator on Floor 7.