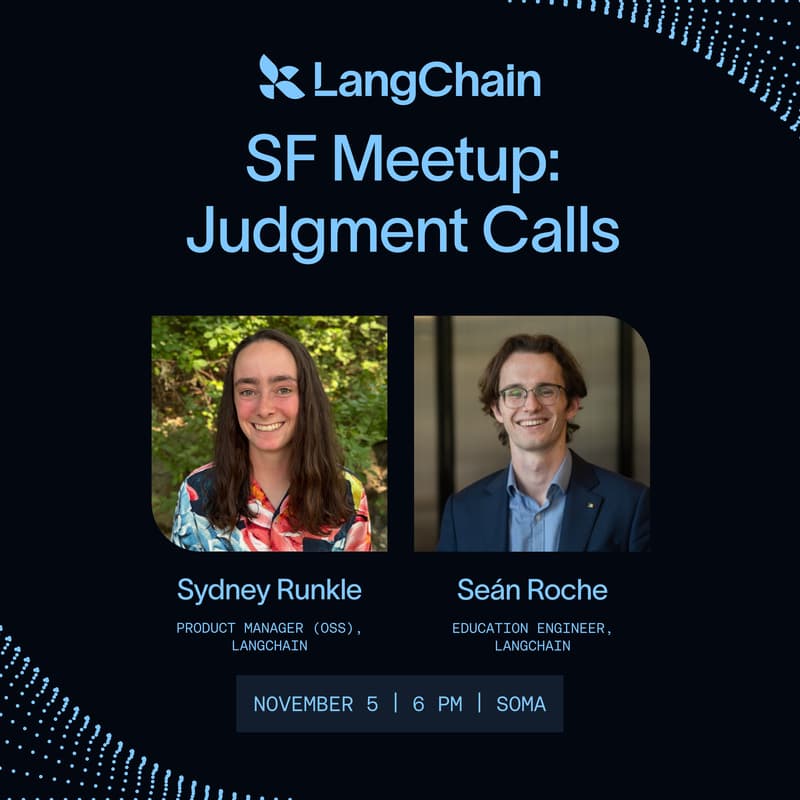

LangChain SF Meetup: Judgment Calls
Join us in San Francisco (SoMa) for a night of talks on building with decision models and using them to evaluate agents. Sydney Runkle, a Product Manager on our OSS team, will show how to pair Jev with LangGraph to build agents that hold up in production. Seán Roche, an Education Engineer, will cover Jev as a judge for agent evals.
🎤 Talk 1: Decision Models and LangGraph with Sydney
Most agents send every decision through a frontier LLM, even when a simple yes or no would do, paying for that generality in latency and cost on every call. In this talk, we pair Jev, TypeSafe AI’s decision model that returns typed answers with probabilities, with LangGraph for routing, durable execution, human-in-the-loop interrupts, and LangSmith tracing. You’ll see a litigation document review graph that sends each page to set aside, redact, or attorney review, how Browserbase cut median Stagehand act() latency from 1.97 to 0.46 seconds in early testing, and where Jev hands off to an LLM when it isn’t confident.
🎤 Talk 2: Jev as a judge with Seán
Code-based evals are fast but narrow, and LLM judges are flexible but slow, expensive, and inconsistent. We tested a third option: Jev, a model from TypeSafe AI that returns typed answers and probabilities instead of generating text. Using Deep Agents and LangSmith, we replayed the same agent runs against Jev, GPT-5.6 Luna, GPT-5.6 Terra, and Claude Sonnet 4.6, comparing accuracy, consistency, latency, and cost. Jev matched human labels on every pass/fail call at about $0.00035 per judgment, though our weather-agent test was small. Cheap evals still need human review, so a consistently wrong judge doesn’t scale its mistakes.
Agenda ⏰
6:00 PM: Welcome + Refreshments
6:30 PM: Presentation with Sydney - Decision Models and LangGraph
6:45 PM: Q&A
6:55 PM: Presentation with Seán - Jev as a judge
7:10 PM: Q&A
7:20 PM: Networking
8:30 PM: Event Ends
Event info:
🎤 Please note this event is fully in-person and will not be live-streamed or recorded.
📍 Location: SoMa — Address provided upon approval.
🎟️ We can only admit guests with approved registrations.
About the host:
LangChain enables every company to own their intelligence. LangChain's open, model-agnostic harnesses give teams choice and control over how they build their agent architecture. LangSmith brings testing, deployment, and monitoring together so teams can continuously improve their agents, compound intelligence, and govern them at scale. More than 7,000 customers, including Nvidia, Bridgewater, LinkedIn, Workday, Harvey, and Rippling trust LangSmith to improve their agents across the Agent Development Lifecycle. Learn more: www.langchain.com