

MLn Club (ML Reading Group) #12: Towards Monosemanticity
Welcome to Week 12: Towards Monosemanticity — Decomposing Language Models With Dictionary Learning
Can we identify meaningful, human-interpretable features inside a language model when individual neurons are polysemantic and represent many unrelated concepts at once?
Can sparse autoencoders recover the hidden features represented in superposition—and give us a better unit for mechanistic interpretability than neurons themselves?
Choose your own readings:
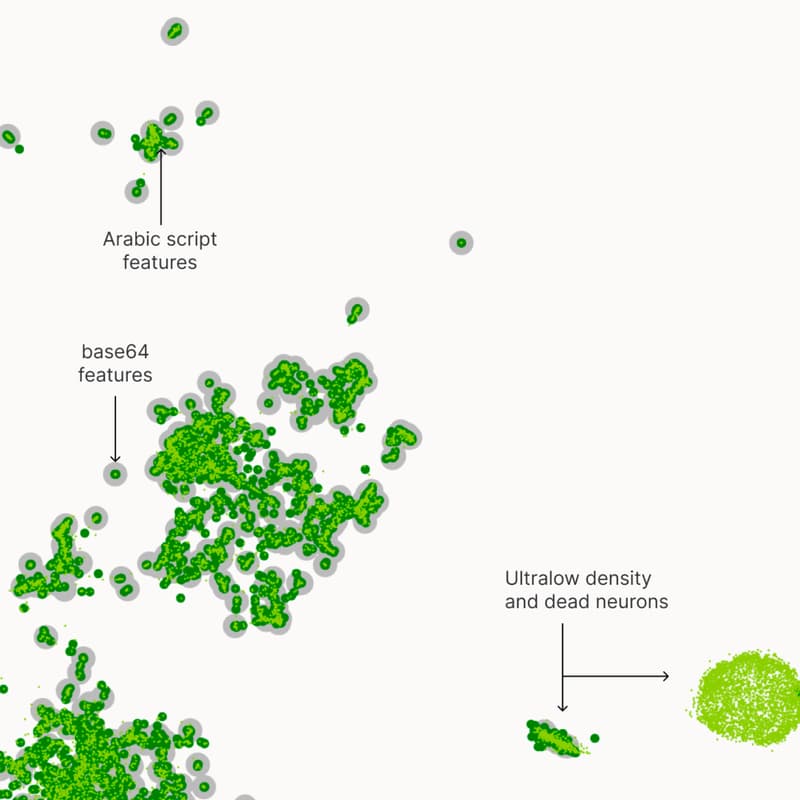
Anthropic’s Towards Monosemanticity investigates whether sparse autoencoders can decompose a language model’s activations into interpretable features hidden by superposition. Rather than treating individual neurons as the fundamental units of computation, the authors train overcomplete sparse autoencoders to reconstruct a transformer’s MLP activations as sparse combinations of learned feature directions—revealing concepts such as Arabic script, DNA sequences, Base64, and Hebrew that may be distributed across many neurons.
The resulting features are substantially more interpretable than neurons and can also behave as causal units: artificially activating features can steer the model toward the corresponding behavior, such as generating Base64 or Arabic text. The paper also uncovers deeper structure, including feature splitting as dictionary size increases, similar features appearing across independently trained models, and groups of features interacting in ways resembling finite-state automata. Together, these results provide an early proof of concept for sparse autoencoders as a tool for mechanistic interpretability, suggesting that models may be better understood in terms of learned features rather than their raw neuron basis.
Join us at CASI for discussion at 8 pm, and (optional) quiet reading from 7 pm.
📖 Reading Recommendations, Questions, or Comments? Contact us here!
🔎 View past meeting notes here.
What's this?
A super warm group of folks discussing their favorite topics!
In the first half, we host an optional quiet reading space
In the second half, we have a discussion where people can talk about what they found interesting about the reading and ask questions about things they didn't understand
When/Where:
CMU AI Safety Initiative's Office, 201 Craig Street, right across the PNC bank. Look for the open door up the stairs.
8pm discussion, 7pm optional quiet reading time.
Here's how it usually goes:
7:00 PM — arrival and settling in
8:00 PM — introductions
8:10 PM — discussion time
9:00 PM — wrap up then open discussion
Who's it for?
People who've been wanting to read up on the latest papers in ML and other fields but just haven't been able to find the time/motivation.
Why:
We've been procrastinating too much on our readings, even though we have so much fun doing them. We know we're not alone in this and want to keep others accountable for learning more about what they're passionate about!
We've also met a ton of really fun friends by discussing what we care about!
Rules/guidelines on how to act:
Act like a host, include people in conversations, talk to people even if they're strangers, offer to explain what you know, and keep an open mind! come to read stuff and find super fun friends :)
Bring snacks if you're feeling kind!