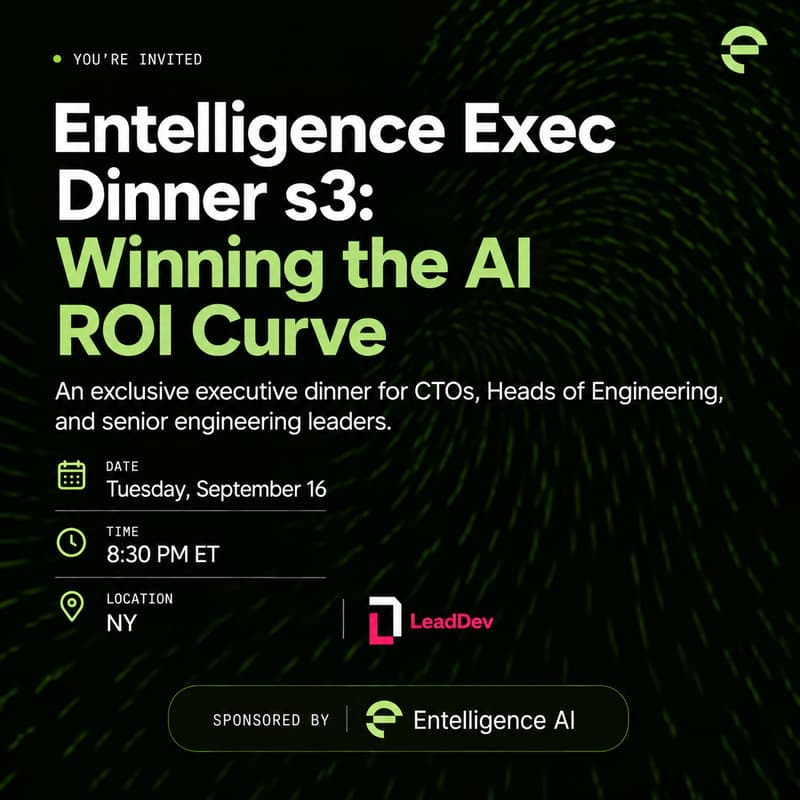
LDX3: Entelligence Executive Dinner s3
AI ROI: Executive Dinner Series
Join us for a relaxed dinner conversation on where agentic coding is headed next - from managing runaway AI costs to keeping AI-generated code production-ready at scale. So much is changing so fast, here's a dinner to make sense of where everyone is at with the latest in engineering agents.
Discussion topics:
Are you really optimizing your engineering team's performance with agents?
Token-maxxing vs. outcome-based AI budgeting - how do you map spend to actual engineering goals?
Can you trace token expenditure back to specific projects, or is it still a black box?
What's really driving cost-per-turn at scale - model choice, routing, or inefficiency?
Is smarter model routing the biggest lever for cutting costs without hurting quality?
How much AI-generated code survives in production without triggering incidents?
What's the gap between "shipped fast" and "still stable six months later"?
EntelligenceAI:
EntelligenceAI is the agent optimization layer for your engineering agents. We measure what your agents ship, what they cost, where they break with repeated bugs, and and optimize your agent performance at enterprise scale.
Built for engineering leaders who need AI-generated code to actually hold up in production.