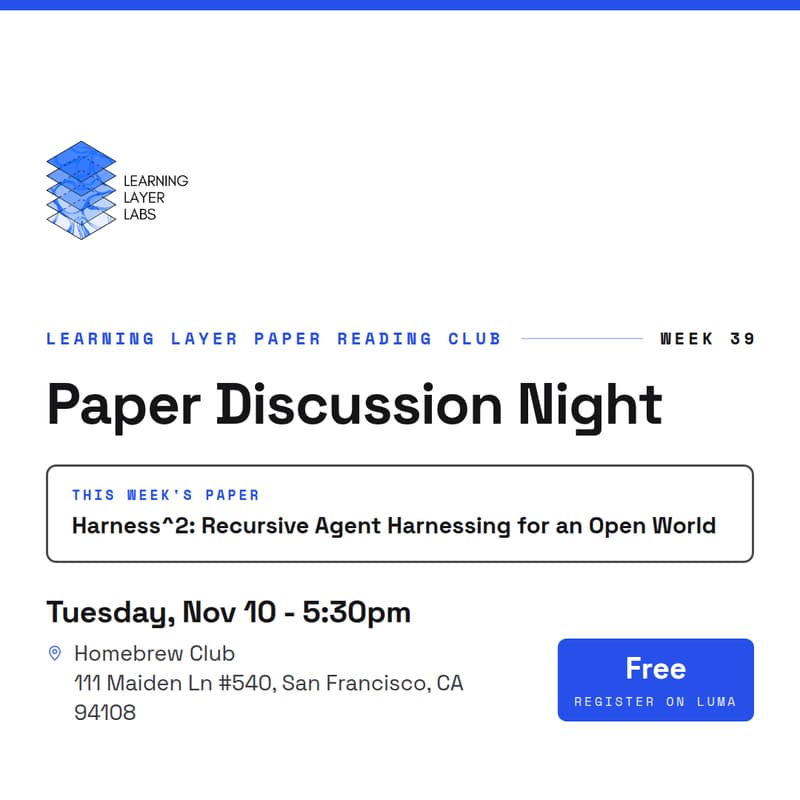

Learning Layer Paper Reading Club - Week 39 - Harness^2: Recursive Agents
This week's paper: Harness^2: Recursive Agent Harnessing for an Open World
Link: https://arxiv.org/abs/2610.14224
Abstract:
How well an LLM agent does depends on two things: the model, and the harness around it (the prompts, tools and control flow that wrap each run). Harnesses are usually hand-tuned per task, and self-improvement methods that try to automate this hit two walls in open-world settings: new tasks have no ground-truth verifier to say whether an edit helped, and improvements learned on one task rarely carry over to the next.
Harness^2 is a plug-and-play framework that evolves harnesses with two levels of recursion. Task-level recursion refines the harness for a single task through a contrastive Propose-Probe-Compose step, and can be scaled by running it in parallel or in sequence. Harnessing-level recursion then distills what worked across those edits into a continual-improvement harness that starts future tasks from a better place.
Across three professional benchmarks and four model-harness setups, a single step improves GLM-5 and Gemini 3.5 Flash over their base harnesses, with gains of up to 11.5 points on WorkBuddy-Bench, 4.5 on JobBench and 11.8 points on LAB, and results keep improving as the task-level budget grows.
Discussion Topics:
With no ground-truth verifier, what is the contrastive Propose-Probe-Compose step actually using as a signal, and how much can we trust it?
Is the harness or the model the bigger lever? Do these gains persist as base models get stronger?
Does experience extracted at the harnessing level generalize, or does it overfit to the benchmarks it was built on?
How does cost scale with the task-level recursion budget, and when is it worth it versus a better model?
What failure modes appear when an agent is allowed to rewrite its own harness?
Are the benchmarks (WorkBuddy-Bench, JobBench, LAB) representative of "open-world" work?
Relevant to anyone building or evaluating LLM agents, or curious about self-improving systems. No preparation required — come read and discuss with us.
What is the Learning Layer Labs Paper Reading Club?
An initiative from https://www.learninglayer.ai, a lab with the goal of reducing AI anxiety in the world.
What is the format?
Discussion based. Expect a low pressure environment to share insights and opinions with the group.
What are the group goals?
Stay on top of AI research and improve understanding of AI fundamentals + math.
Who is welcome?
Everyone! Try to put in at least some time on the paper and come prepared with questions or things you'd like to discuss, but it's ok to just show up!
Learning Layer Labs team:
Thomas Redfern ( The backbone who runs every paper reading )
Mat Allen (The new fella bring order and organization)
Devinder Sodhi (The guy you talk to for sponsoring)