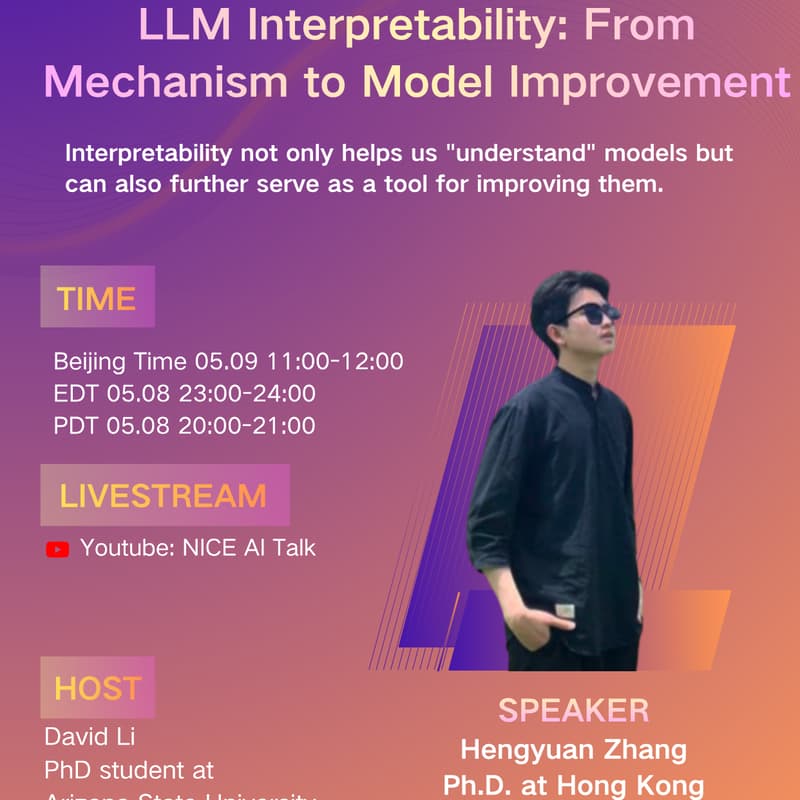
LLM Interpretability: From Mechanism to Model Improvement (NICE No.169)
NICE Talk No 169 invites Zhang Hengyuan, first-year Ph.D. student at HKU Ngai Lab, to share on LLM Interpretability: From Mechanism to Model Improvement.
Why does a model produce a certain behavior? Where are capabilities stored — in which layers, modules, or representations? And can understanding these internals help us improve the model itself?
This talk covers three lines of work:
1. [Locate, Steer, and Improve] A practical survey of actionable mechanistic interpretability in LLMs — organized as a Locate → Steer → Improve pipeline.
2. NSDS — a data-free layer-wise mixed-precision quantization method driven by numerical and structural dual-sensitivity, guided by interpretability analysis.
3. ShifCon — enhances non-dominant language capabilities via shift-based contrastive learning on multilingual representation subspaces.
Core insight: Interpretability is not just about "seeing" how a model works — it can be a tool for improving it.
Speaker: Hengyuan Zhang, HKU Ngai Lab. Research focuses on LLM mechanistic interpretability. Published at ACL, NeurIPS, CVPR, EMNLP, TKDD and more.
Homepage: https://rattlesnakey.github.io/
Paper 1: https://arxiv.org/pdf/2601.14004
Paper 2: https://arxiv.org/pdf/2603.17354
Paper 3: https://arxiv.org/pdf/2410.19453