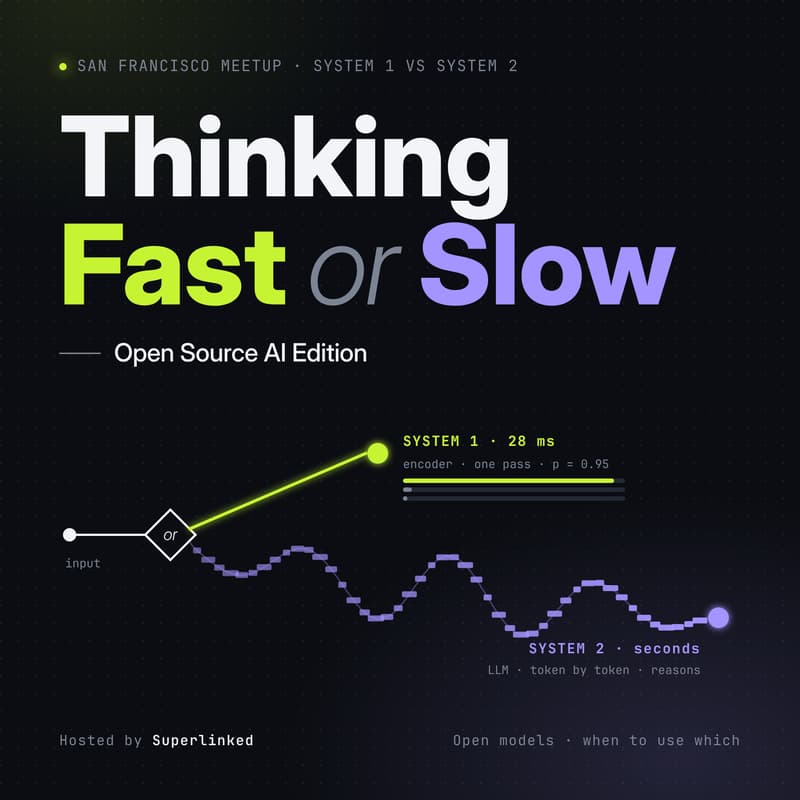
TBA - Thinking Fast or Slow: Open Source AI Edition
Most agents send every decision to the slowest, most expensive brain in the stack. Is this ticket about billing? Is this prompt trying to hijack the agent? Each of those has a handful of possible answers, and a frontier LLM answers it by writing prose about it.
Kahneman split thinking into System 1 (fast, automatic, cheap) and System 2 (slow, deliberate, expensive). Agent stacks now have the same split: small decision models that answer in milliseconds with a calibrated probability, and LLMs that plan and reason. This evening is about choosing between them — when fast is good enough, when you need slow, and how to build the handoff.
Who Should Come
AI engineers building with or choosing between System 1 and System 2 models. Maybe you’re trying a hosted decision API, running GLiClass or GLiNER yourself, or still sending every yes/no to an LLM and watching the bill. Platform and infra folks serving these models are welcome too.
What to Expect:
Fast or slow, demystified (Rahul Parundekar). A working framework for when to use which model. Comparison with 2019-era zero shot ML models, vs structured output/JSON-mode, latency, cost, accuracy and calibration tradeoffs, and the limitations: confidence vs accuracy, black-box nature, etc.
Inside the fast models (Daniel Svonava, founder Superlinked). How encoder decision models (GLiClass, GLiNER, Laya) answer every option in one forward pass, where zero-shot breaks, and what changes when you tune on your own labels.
Talk 3: (TBD)
Food, drinks, and engineers comparing notes.
NOTE: We're trying to put together a great event and location and agenda is subject to change.