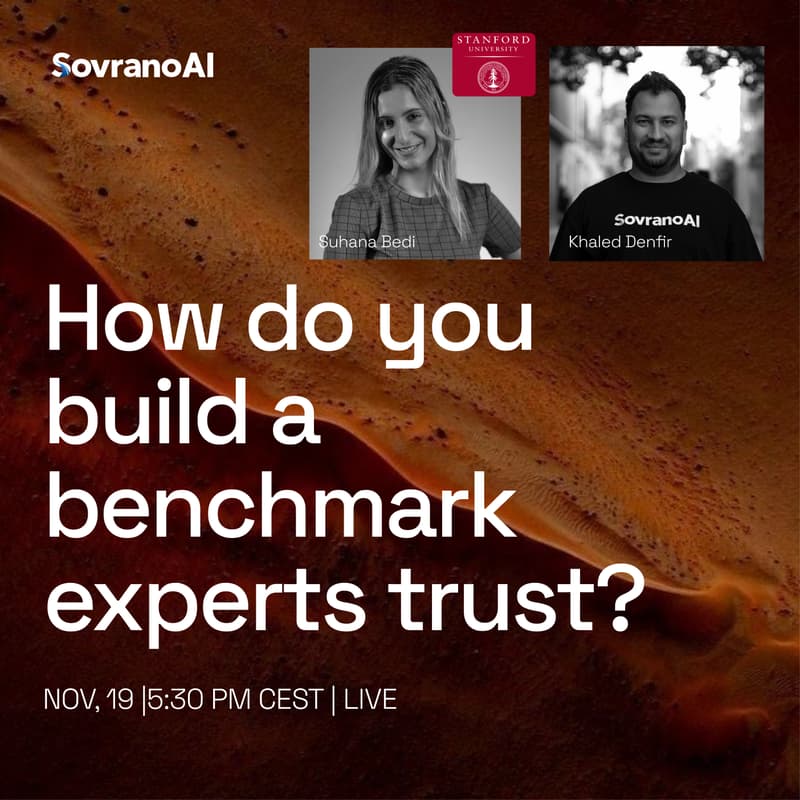

Live Session: How do you build a benchmark experts trust?
Most AI benchmarks are built to be scored by a machine. These two were built to be judged by experts.
Suhana Bedi (Stanford, lead author of MedHELM) and Khaled Denfir (Head of Project Delivery at Sovrano, EuroExec) both built evaluations where domain experts decide what a good answer looks like: clinicians in medicine, experienced professionals in executive decision-making.
In this live conversation they’ll compare the decisions behind both benchmarks:
→ How they found and vetted the experts
→ How to design rubrics experts actually agree on
→ When an LLM judge can do the experts’ job, and when it can’t
→ What it cost, and what they’d do differently
When: Thursday, Nov 19 · 17:30 CET / 8:30am PT
Format: 45 min on Zoom. 30 min conversation + 15 min live Q&A
Who it’s for: researchers and ML teams working on evaluation, benchmarks or domain-specific models.
No product pitch. Just the details that rarely make it into a paper. Bring your questions.