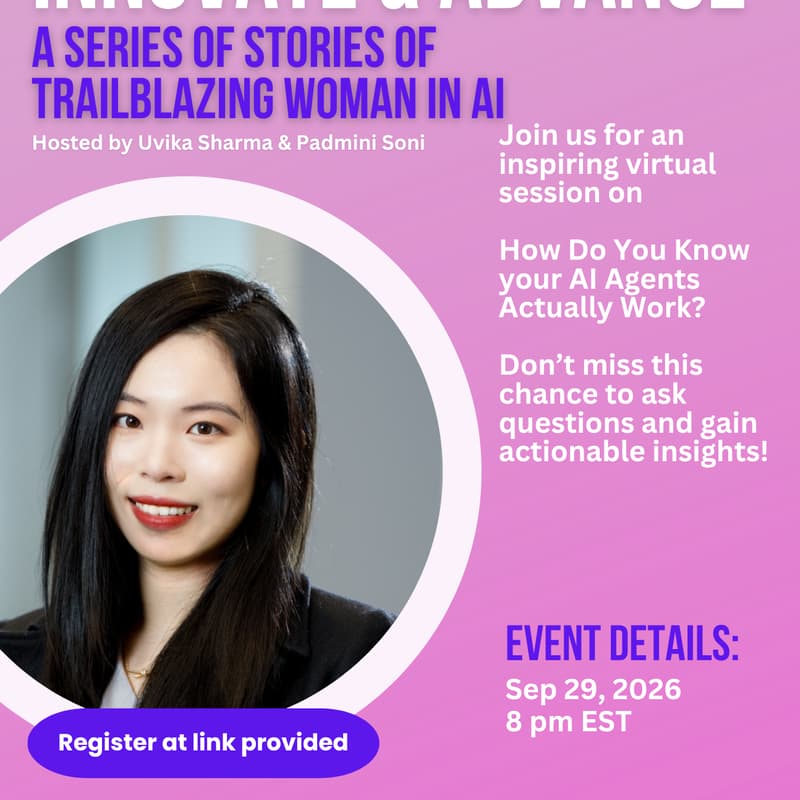
AWAAI Innovate & Advance with Helen Yang
We’re building AI agents faster than we’re learning how to tell whether they actually work.
A slick demo is one thing.
But would you deploy that agent into a real business process?
How much human oversight does it need?
Is the more expensive model actually performing better?
And what does “good” even mean?
These are exactly the questions Padmini Soni and I are incredibly excited to dig into at our next Asian Women Advancing AI (AWAAI) Innovate & Advance session with Helen Yang, Enterprise Lead at Mercor.
𝗛𝗼𝘄 𝗗𝗼 𝗬𝗼𝘂 𝗞𝗻𝗼𝘄 𝗬𝗼𝘂𝗿 𝗔𝗜 𝗔𝗴𝗲𝗻𝘁 𝗔𝗰𝘁𝘂𝗮𝗹𝗹𝘆 𝗪𝗼𝗿𝗸𝘀?
Helen is going to take us beyond “the output looks pretty good” and into how agent evaluation actually works.
You’ll learn how to:
→ Break an evaluation into the task, environment, expected output, rubric, and verifier
→ See how evals expose meaningful differences in agent performance
→ Translate evaluation results into real decisions about deployment, human oversight, and model cost
If you’re building, buying, deploying, or governing AI agents, this is becoming a capability you need to understand.
Because we need to stop asking whether:
Can we build an AI agent?
But:
Can we prove it works well enough to trust with real work?
Join us on September 29. We would love to have you there.