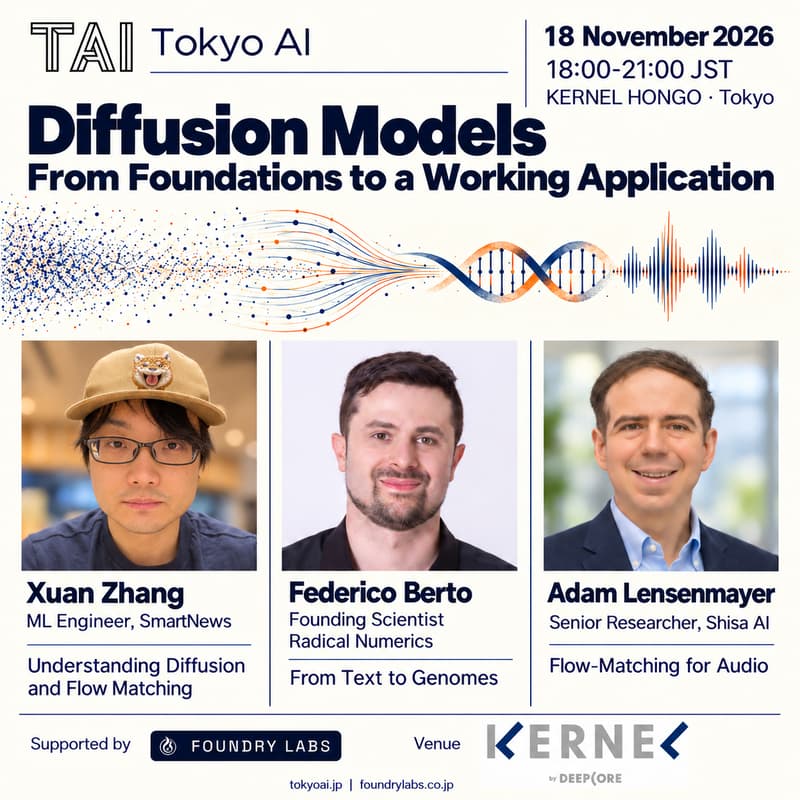

Diffusion Models: From Foundations to a Working Application
A Tokyo AI technical session exploring diffusion models, from flow matching and core design choices to diffusion language models and applications in biology and speech synthesis.
Join us on Wednesday, November 18, 2026, 18:00-21:00 JST, at KERNEL HONGO for three technical talks spanning diffusion and flow-matching foundations, genome foundation models, and a hands-on route to text-to-speech.
What we will explore
Foundations of diffusion and flow matching.
Diffusion language models and their design choices.
Diffusion language models and genome foundation models, from RND1 to Omnii.
Flow matching for audio and a from-scratch TTS model for hobbyist hardware.
Who should attend
ML practitioners, AI engineers, researchers and research students interested in understanding diffusion models through technical explanations and concrete examples.
Agenda (provisional)
18:00 - Doors open
18:25-18:30 - Welcome
18:30-19:00 - Talk 1: Understanding Diffusion and Flow Matching (Xuan Zhang)
19:00-19:30 - Talk 2: From Text to Genomes: Diffusion Language Models and Foundation Models for Biology (Federico Berto)
19:30-20:00 - Talk 3: Flow-Matching for Audio: Learn From the Latest Models and Build Your Own TTS Model (Adam Lensenmayer)
20:00-21:00 - Networking
21:00 - Doors close
Talk slots include Q&A. The running order and individual timings are provisional.
Talk 1: Understanding Diffusion and Flow Matching
Xuan Zhang, Machine Learning Engineer, SmartNews
This talk will introduce the core ideas behind diffusion models and flow matching, with an emphasis on intuition rather than mathematical derivation. I’ll focus on the physical intuition behind the generative process, how the main ideas connect, and use a few demos to make the concepts more concrete. I may also include some recent developments as I prepare the final talk.
About the speaker
Xuan Zhang is a machine learning engineer at SmartNews in Tokyo, working on recommendation systems and large-scale ML systems. He previously worked on computer vision and deep learning research at Megvii, and later on computer vision applications at Ant Financial. His current interests include generative modeling, representation learning, and practical ML systems.
The talk title and abstract are provisional and may be refined before the event.
Talk 2: From Text to Genomes: Diffusion Language Models and Foundation Models for Biology
Federico Berto, Founding Scientist, Radical Numerics
This talk covers diffusion language models: how they differ from autoregressive LLMs, where the current state of the art stands, and what they make possible, such as parallel decoding and infilling. I'll start from RND1, our open-source diffusion LLM, and share a few lessons from scaling it. Then I'll move to biology, where DNA, proteins and other omics can be modeled as language too and show what genome foundation models like Omnii can do by understanding the language of life.
About the speaker
Federico Berto is a Founding Scientist at Radical Numerics in Tokyo, focusing on pretraining bio and language models. He received his PhD from KAIST, where he worked on foundation models for combinatorial optimization and founded the AI4CO open research community. His current interests include generative modeling for biology and scaling alternative architectures.
Talk 3: Flow-Matching for Audio: Learn From the Latest Models and Build Your Own TTS Model
Adam Lensenmayer, Senior Researcher, Shisa AI
This talk will cover the basic ideas behind flow matching for audio, specifically Text-to-Speech: how we use it, why we use it, and what the tradeoffs are versus other architectures. We'll take a brief look at how flow matching is used in the latest TTS models like Voxtral and the just-released Phonon TTS, as well as share a simple from-scratch flow-matching TTS architecture that you can experiment with at home on hobbyist-level hardware.
About the speaker
Adam Lensenmayer is a senior researcher at Shisa AI, specializing in multilingual and multimodal AI models. His primary research interests include the development of high-performance, low-latency models for audio and translation. He also works in the field of AI safety, including AI debiasing and AI for fraud detection as part of the Japanese NEDO GENIAC-PRIZE project.
The talk title is proposed and may be refined before the event.
Location
KERNEL HONGO, 3F, 4-1-4 Hongo, Bunkyo City, Tokyo 113-0033, Japan.
Supporters
Special thanks to our supporters in this session:
Foundry Labs K.K. is a Tokyo-based AI systems integrator and solutions provider, supporting enterprises from strategy and implementation through deployment and operations.
DEEPCORE supports AI and deep-tech startups and operates KERNEL, the AI incubation community hosting this session in Hongo.
Organizer
Hosted by Tokyo AI (TAI), organized by Ilya Kulyatin, founder of Foundry Labs株式会社.
Privacy Policy
We will process your email address for the purposes of event-related communications and ongoing newsletter communications. You may unsubscribe from the newsletter at any time. Further details on how we process personal data are available in our Privacy Policy.