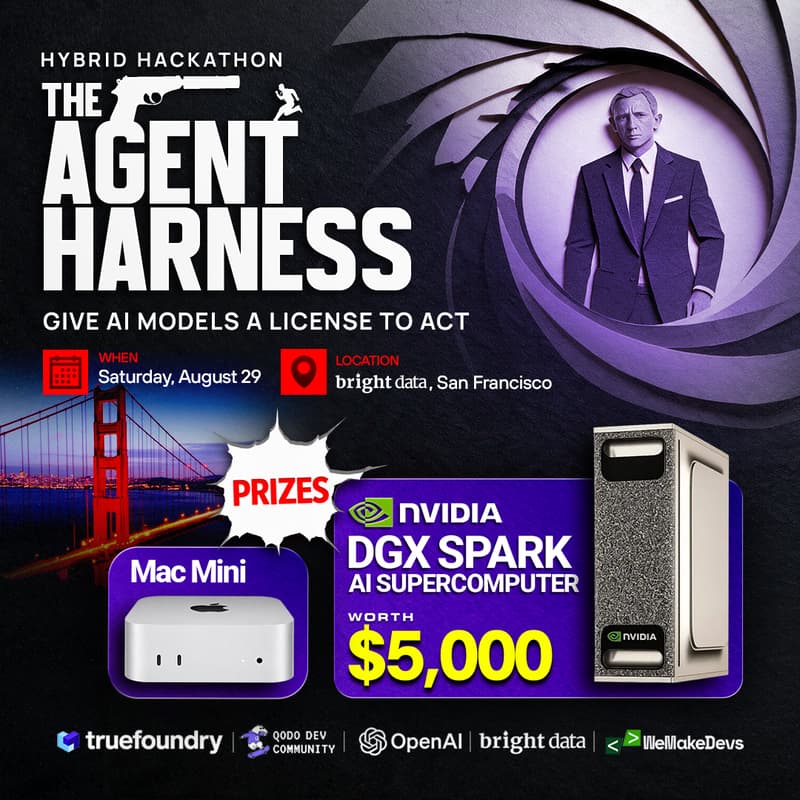

Agent Harness Hackathon | Win an NVIDIA DGX Spark AI Supercomputer
You get an agent working in an afternoon. Then you point it at something that matters and it can't reach your tools, can't run its own code safely, and can't be stopped before it does damage. Spend a day building one that can do all three.
👉 Submit your projects here
📅 Agenda
09:00: Doors and check-in open
09:00 - 09:45: Breakfast 🥯
09:45 - 10:00: Kickoff speech
10:00 - 11:00: Workshops
11:00 - 14:00: Hacking
14:00: Pizza time 🍕
14:00 - 17:00: Hacking continues
18:00: Project submission deadline ‼️
🧑💻 What you are building
A working AI agent, in a day. Pick a job worth handing to an agent, in any field you like, and build the agent that does it. Devtools, operations, data, consumer apps, multi-agent systems: the domain is yours.
A chatbot answers questions. An agent acts on them: it opens the pull request, queries the database, runs the script, sends the message. That is the bar. Bring an idea or pick one up when you arrive.
🏆 Prizes
A team can win one track, not all! BUT you can apply to multiple tracks to increase your chances of winning.
Best Use of the Agent Harness: NVIDIA DGX Spark Personal AI Supercomputer, worth $5,000. Presented by TrueFoundry. For the agent that gets the most out of the harness. What matters is that the harness is doing the work rather than sitting underneath a thin wrapper.
Best Code Quality: Mac Mini. Presented by Qodo. For the team that treats a hackathon repo like real software. Run your pull requests through Qodo and deal with what it finds before you merge. Using Qodo is required for this track.
Best use of Bright Data: Apple AirPods 4. For the team that scrapes live web data best and keeps it flowing when sites change.
Best UI: iPad. For the team whose agent is something a stranger could pick up and drive. An interface that shows what the agent is doing, what it is waiting on, and what it did, and asks before the irreversible step rather than after it.
Best LinkedIn post: Keychron keyboard. Write up what you built, how you wired it together, and what broke along the way. Please make sure to tag WeMakeDevs, Qodo, TrueFoundry and Bright Data.
🛠️ The tools
1️⃣ TrueForge
You will build on an open-source agent harness, introduced in the morning workshops. A harness is the layer between a model and everything it acts on. It runs the loop your agent works in, sending the model its instructions, calling the tools it asks for, feeding results back, and keeping context and session state across turns. Practically, that means you get:
Connections to your tools. Any MCP server, including ones behind OAuth, plus built-in tools and web search.
Sandboxed execution. Agent-written code runs somewhere isolated.
Human approvals. Pause before sensitive actions until a person signs off.
Subagents. Delegate parts of a job to other agents.
Sessions that survive reconnects. A run keeps going through a refresh or a restart.
Any model provider. OpenAI, Anthropic, Gemini, or any OpenAI-compatible endpoint.
Skip the plumbing and spend the day on the agent itself.
2️⃣ Qodo
Qodo is an AI code review platform. Its agents review your pull requests against your full codebase rather than just the diff, flag real bugs and breaking changes ranked by severity, and can apply the fix.
3️⃣ Bright Data
💰Get $50 in credits by signing up here or using code "wemakedevs" in billing section.
Every factory runs on raw material. For your agents, that raw material is live web data, and the web doesn't sit still. Pages change, layouts shift, and a scraper that worked at 2 PM can silently fail by demo time.
Your challenge is to build your web data pipeline using Bright Data directly inside your coding assistant terminal (these are just ideas, use the platform as you wish):
Extract web data through terminal commands without switching back and forth to a web browser dashboard.
Save your scraper settings inside your project rules file (like
CLAUDE.md,.cursor/rules, orCODEX.md) so your assistant reuses them automatically.Show automatic scraper repair when a target website updates its HTML structure.
We'll be looking at:
How cleanly your data pipeline lives inside your agentic workflow, not beside it
Whether your scraper configuration is reusable and version-controlled, not a one-off command
How your pipeline detects and recovers when a target site changes underneath it
Whether the data feeding your factory is fresh, structured, and actually used by your app
A hardcoded HTML parser is not a data pipeline. A good pipeline notices when the web changes, repairs itself, and keeps the factory fed.
Before the hackathon
Get set up via the Bright Data link.
Run Scraper Studio from your terminal and pull data from one site end to end.
Add your scraper settings to your project rules file and confirm your coding assistant picks them up automatically.
Break something on purpose: point at a page whose structure has changed and watch the auto-repair flow.
Don't just scrape a page once. Show us a pipeline that keeps working when the web doesn't.
4️⃣ OpenAI
OpenAI is providing $50 in credits to everyone who attends, so you are not paying to experiment.
💡 Project ideas
Start from one of these, or bring your own.
Code review agent. Reads a pull request, runs the test suite in a sandbox, and comments on what it found.
Incident responder. Investigates an alert with read-only queries, then asks a person before restarting or rolling anything back.
Analytics agent. Answers questions in plain English by writing the SQL itself, running it, and explaining the result.
Research desk. Sends subagents across the web on a single question and merges what they find, with sources.
Approval-gated assistant. Drafts the email, files the ticket, or books the trip, and does nothing irreversible until you approve it.
Untrusted code runner. Executes code submitted by someone else inside an isolated sandbox and returns the result safely.
👇 Details
Teams of one to four. Free to attend. Come on your own and find people there. Your repo needs to be open source.
Bring a laptop, a charger, and ID for venue entry. Food and Wi-Fi are covered.
Open to platform, infrastructure, and backend engineers, anyone working with LLMs, tool calling, or MCP, founders taking an agent prototype further, and anyone who wants to build their first agent without writing the runtime themselves.
Judges:
Adam Eliezerov, Co-Founder & CTO at Arbium
Kunal Kushwaha, Founder of WeMakeDevs
Sai Krishna, FDE at TrueFoundry
David Perry, Principal Architect at Qodo