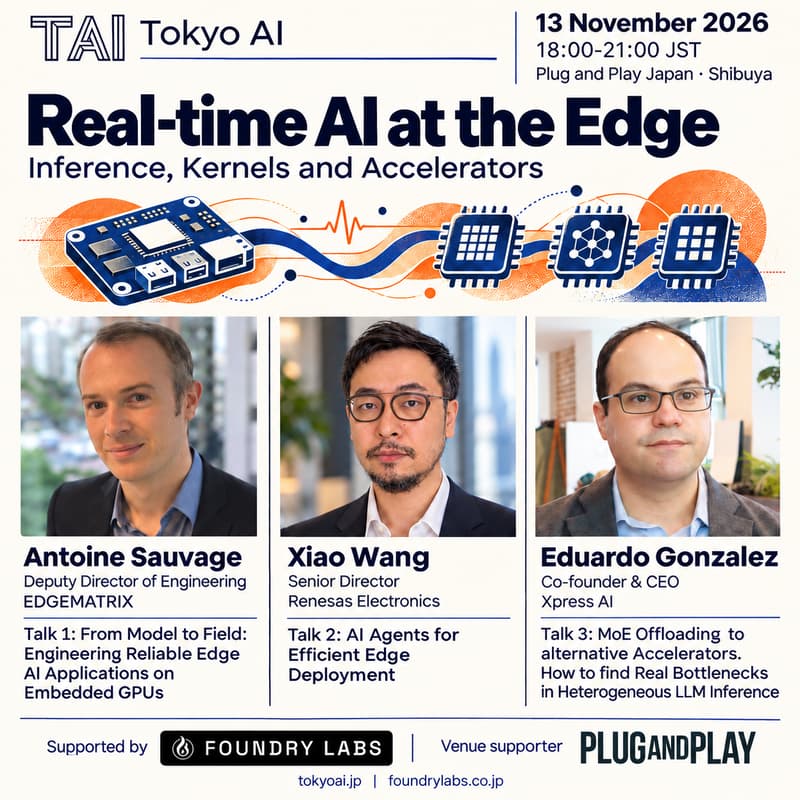

Real-time AI at the Edge: Inference, Kernels and Accelerators
Description
How do you make AI respond quickly when compute, memory and power are limited? Join Tokyo AI (TAI) for a technical evening exploring the systems work behind efficient inference, from GPU profiling to reliable embedded applications and agent-assisted deployment.
Designed for ML engineers, systems developers and engineers building edge AI products, the session will connect low-level implementation choices with the latency and reliability people experience in real applications.
Three technical talks cover:
Engineering reliable real-time computer vision applications on embedded GPUs, from model deployment to field operations.
Using AI agents to coordinate hardware-aware optimization, reuse deployment knowledge and validate results.
Profiling heterogeneous LLM inference and offloading MoE experts to alternative accelerators.
When: Friday, November 13, 2026, 18:00-21:00 JST.
Where: Plug and Play Japan, Shibuya. Register for venue details.
Agenda
Each 30-minute talk includes Q&A.
18:00 - Doors open
18:25-18:30 - Welcome
18:30-19:00 - Talk 1: From Model to Field: Engineering Reliable Edge AI Applications on Embedded GPUs (Antoine Sauvage)
19:00-19:30 - Talk 2: AI Agents for Efficient Edge Deployment (Xiao Wang)
19:30-20:00 - Talk 3: MoE Offloading to alternative Accelerators. How to find Real Bottlenecks in Heterogeneous LLM Inference (Eduardo Gonzalez)
20:00-21:00 - Networking
21:00 - Doors close
Talks
Talk 1: From Model to Field: Engineering Reliable Edge AI Applications on Embedded GPUs
Speaker: Antoine Sauvage, Deputy Director of Engineering, EDGEMATRIX
Abstract:
Getting an AI model running on an embedded accelerator is only one part of building a production Edge AI application. In the field, inference has to coexist with video ingestion, application logic, limited compute and memory, device management, monitoring, and failure recovery.
In this talk, I will share practical lessons from developing real-time computer vision systems on NVIDIA Jetson platforms. I will look at the engineering path from deploying an optimized model to operating a complete application: integrating GPU-accelerated video pipelines, working within embedded hardware constraints, handling unreliable cameras and networks, and designing systems that can be maintained and updated over time.
The focus will be on the gap between getting an AI demo running and building an Edge AI application that can operate reliably in the real world.
Bio:
Antoine Sauvage is Deputy Director of Engineering at EDGEMATRIX in Tokyo, where he works on the architecture and development of Edge AI platforms and applications. He has over 20 years of experience across industrial systems, IoT, cloud infrastructure, and edge computing. His current work focuses on real-time computer vision and the deployment of AI applications on NVIDIA Jetson platforms.
Talk 2: AI Agents for Efficient Edge Deployment
Speaker: Xiao Wang, Senior Director, Renesas Electronics
Abstract:
What if deploying AI on an edge device could become a learning process, with each deployment making the next one easier? This talk explores how AI agents can turn deployment goals into coordinated action, drawing on specialized expertise and memory to navigate hardware constraints. We’ll examine how to build frameworks that learn from experiments, reuse knowledge, and balance autonomous exploration with reliable validation. Attendees will gain a perspective on where agents can reduce engineering effort and how to evaluate their impact on deployment quality and efficiency.
Bio:
Xiao Wang is a Senior Director at Renesas Electronics, where he leads an AI team for system-on-chip platforms. His work focuses on AI compilers, hardware-software co-design, and efficient deployment of AI models on edge devices. His current interests include using AI agents to automate hardware-aware optimization while preserving correctness, measurable performance, and reproducibility.
Previously, he focused on autonomous driving at Woven by Toyota. Before moving to Japan, he worked in the United States through his own startup, Accenture, and projects supporting a federal government agency. He has focused on machine learning and advocated for digital twins since college.
Talk 3: MoE Offloading to alternative Accelerators. How to find Real Bottlenecks in Heterogeneous LLM Inference
Speaker: Eduardo Gonzalez, Co-founder & CEO, Xpress AI
Abstract:
Modern GPUs have far more compute than memory bandwidth, and mixture-of-experts decoding spends most of its time streaming expert weights, not multiplying them. That opens the door to offloading experts to accelerators that offer cheaper bandwidth. We serve large MoE models using NVIDIA A100s and NEC Vector Engines (an accelerator that costs $5–10k.) and achieve performance on par with a B200, at a fraction of the cost. The hard part was not the kernels but figuring out where time goes during inference. When going hybrid, profilers only show you part of the whole story. In a hybrid system such as this the bottleneck moves between the GPU, the host, PCIe, and the vector engines as you optimize. This talk covers how we built an end-to-end measurement set-up for that system (per-layer timing windows, protocol brackets, kernel-level counters on each device), and how each measurement pointed at the next bottleneck: a launch protocol, then stream-operation count, then GPU kernel occupancy. Even if you don't use NEC Vector Engines, this talk shows you the method you should use for any heterogeneous setup.
Bio:
Eduardo Gonzalez is Co-founder and CEO of Xpress AI. He previously served as an assistant professor at Kyoto Seika University and Chief Innovation Officer at Skymind.
Organizers
Ilya Kulyatin is an entrepreneur with work and academic experience in the US, Netherlands, Singapore, UK, and Japan. He holds a BA in Economics, an MA in Finance, and an MSc in Machine Learning. He's a 3x founder, now helping Japan grow the local AI ecosystem through a not-for-profit community, Tokyo AI (TAI), while building an AI-native system integrator and solutions provider, Foundry Labs株式会社.
Supporters
Foundry Labs K.K. is a Tokyo-based AI systems integrator and solutions provider, delivering end-to-end support for enterprises: from strategy design through implementation, deployment, and operations. They tailor AI to each client's operational, regulatory, and security requirements, with hands-on experience across finance, government, and industry, and a track record of shipping production systems in secure and regulated environments.
Plug and Play is one of the world’s most active venture capital firms. It has invested in more than 2,000 companies, including PayPal, Dropbox, and Guardant Health, backing many unicorn companies. In Japan, it began investing in 2019, supporting domestic startups across industries, regardless of whether they participate in its accelerator programs.
About TAI
Tokyo AI (TAI) is the largest international AI community in Japan, with 7,000+ members mainly based in Tokyo: engineers, researchers, investors, product managers, and corporate innovation leaders. Through 80+ events a year and 300+ speakers spanning startups, enterprises, and academia, TAI connects the people building AI in Japan with the global ecosystem, working to transform Tokyo into a global AI hub.
Privacy Policy
We will process your email address for the purposes of event-related communications and ongoing newsletter communications. You may unsubscribe from the newsletter at any time. Further details on how we process personal data are available in our Privacy Policy.