Strange Evals - ProgramBench
Hosted by Louka Ewington-Pitsos & 4 others
Registration
Past Event
About Event
a paper reading club but we deep dive into benchmarks
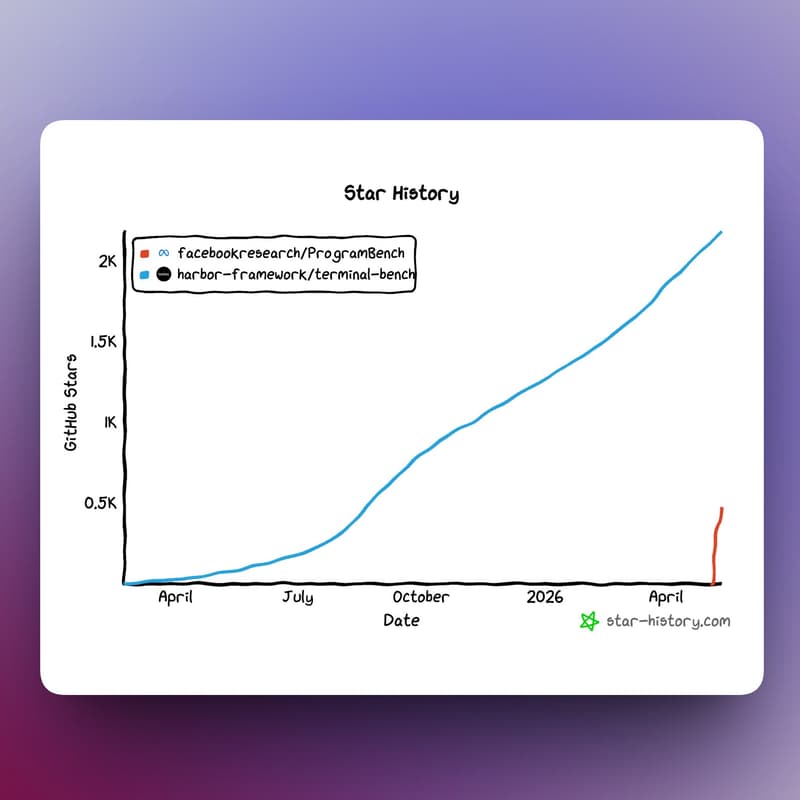
This session: ProgramBench, on which the best SOTA model (gpt-5.5) scores just 1/200. It's growing very rapidly in GitHub stars https://www.star-history.com/?repos=facebookresearch%2FProgramBench%2Charbor-framework%2Fterminal-bench&type=date&legend=top-left and raises questions such as:
Are we looking at the new paradigm, or just a poorly designed benchmark?
Has Openai finally regained the Mandate of Heaven?
I'm currently training a model on this benchmark so should have some interesting insights from this as well!
Pre-reading: spend 15 minutes skimming the highly digestible ProgramBench paper: https://arxiv.org/abs/2605.03546
All Mox members get in automatically.