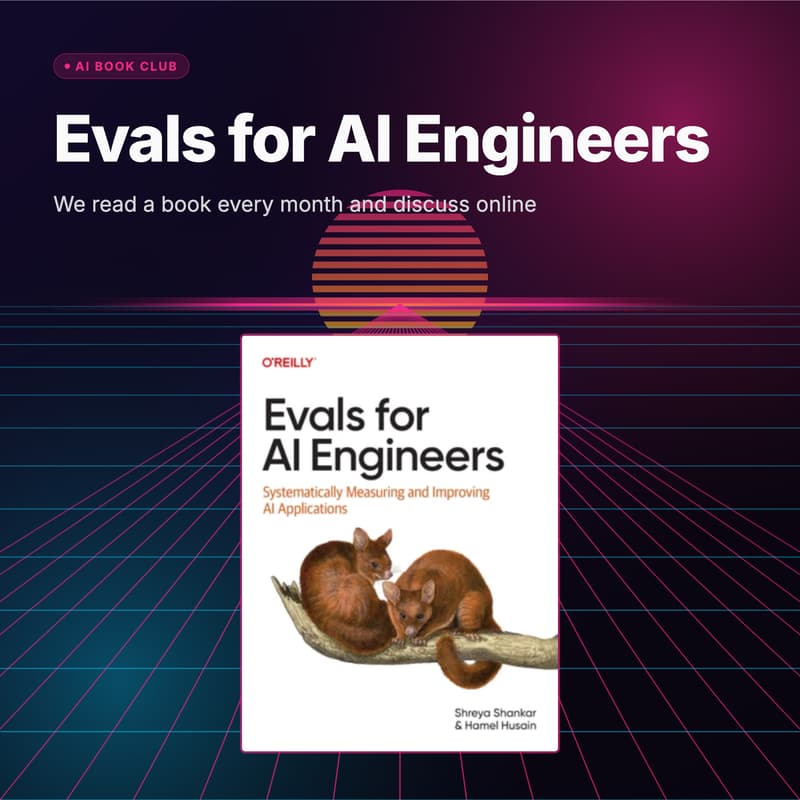

AI Book Club: Evals for AI Engineers
Decembers book is "An Illustrated Guide to AI Agents"!
This is a casual-style event. Not a structured presentation on topics. Sometimes, the discussion even drifts away from the chapters, but feel free to grab the mic to help steer it back.
Feel free to join the discussion even if you have not read the book chapters! :)
Want to discuss the contents during the reading week? Join the Flyte MLOps Slack group.
-------------------------------------------------
About the book:
Title: Evals for AI Engineers
Authors: Shreya Shankar, Hamel Husain
Published: October 2026
O'rielly platform: https://learning.oreilly.com/library/view/evals-for-ai/9798341660717/
Chapters:
Introduction
LLMs and Evaluation Basics
Error Analysis
Collaborative Evaluation Practices
Implementing Automated Evaluators
Evaluating Multi-Turn Conversations
Evaluating Retrieval-Augmented Generation
Evaluating Tool Use and Complex Agents
Continuous Integration and Deployment for LLM Agents
Interfaces for Human Review
Data Analysis for Traces
Improving LLM Agents
Book Description
Stop using guesswork to find out how your AI applications are performing. Evals for AI Engineers gives you a practical framework for systematically testing, measuring, and improving AI applications, especially those built with LLMs. Written by Shreya Shankar and Hamel Husain, AI engineers with extensive experience across 35+ AI products and cutting-edge research, this book focuses on the techniques teams actually need to build reliable AI systems in production.
Ideal for software engineers, technical product managers, and technical leads, this hands-on guide shows you how to build an evaluation process that improves alongside your product.
Find and prioritize failures through systematic error analysis and representative test sets
Build trustworthy evaluations using code based checks, LLM judges, human feedback, and synthetic data
Improve production systems over time by monitoring regressions and optimizing quality, latency, and cost